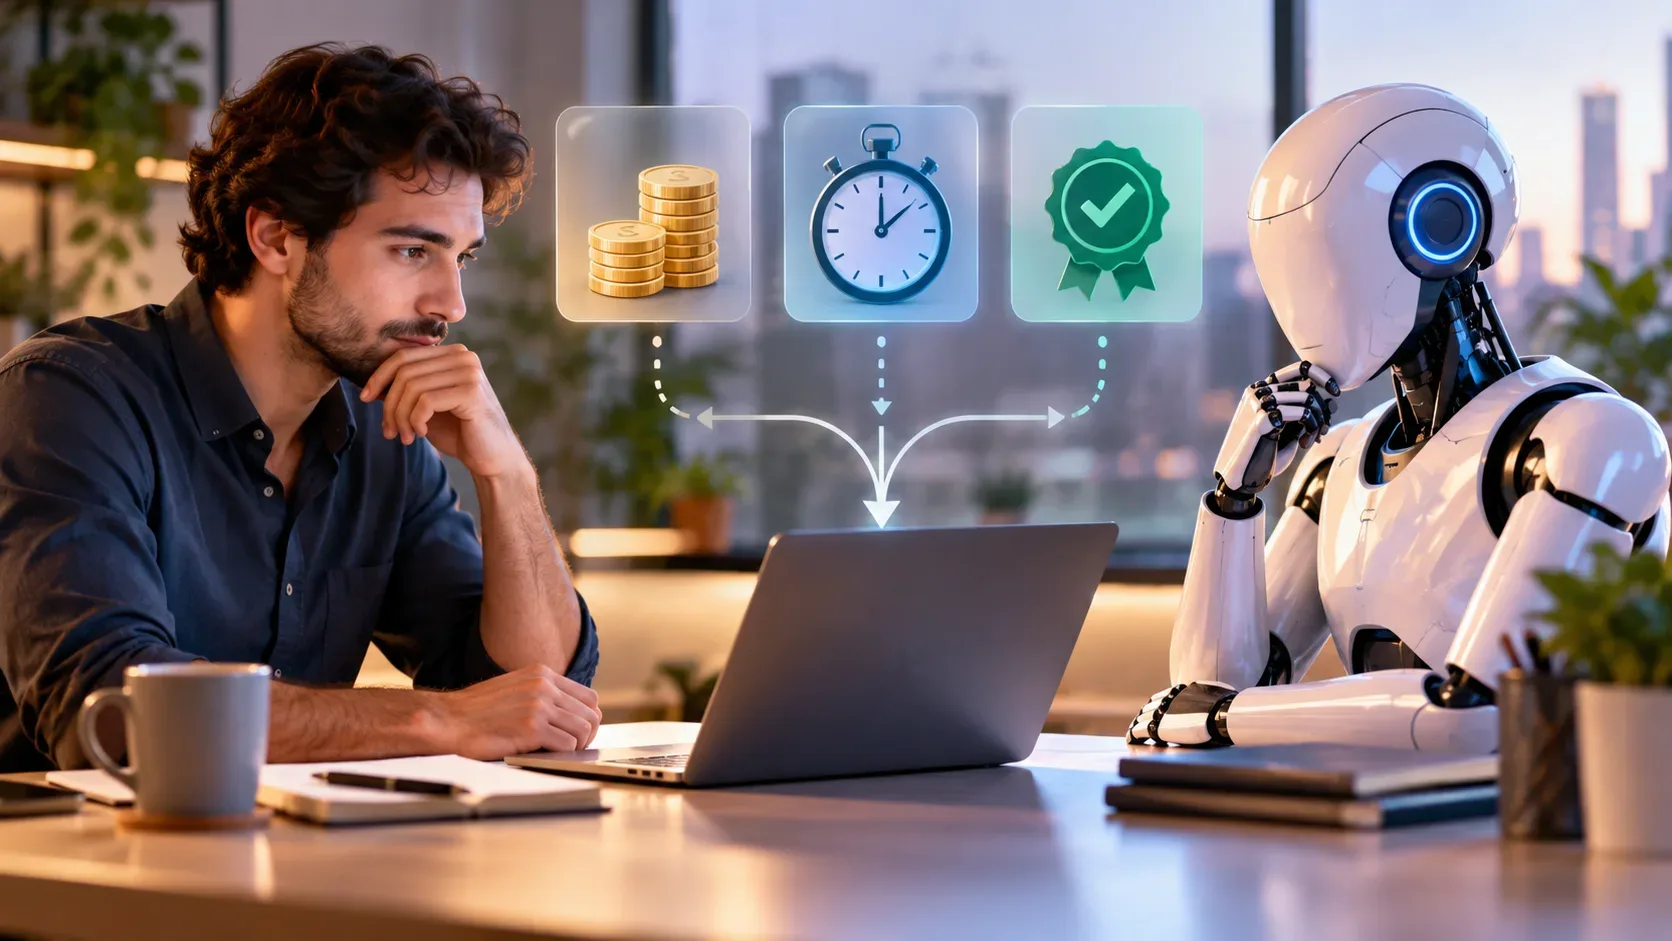
Delegating a task to an AI agent should not be based only on token price or the impression that “the machine is faster.” The useful comparison is between complete ways of getting the work done: human, agent, or hybrid. That means measuring the final outcome, end-to-end time, and total cost — including review, rework, integrations, and risk.
In a column published on June 4, 2026, Microsoft WorkLab uses “tokenomics” in this managerial sense. Based on lessons from a forum with 250 Microsoft customers, it proposes comparing quality, time, and cost and allocating tokens with discipline similar to headcount. It also stresses that these economics change quickly and must be recalibrated. Source: Microsoft WorkLab.
What “tokenomics” means at work
Here, tokenomics has nothing to do with crypto assets. It is a way to manage AI compute resources as economic inputs to work. Tokens are part of the cost, but they are not the final metric. A token-cheap task can become expensive if it requires many attempts, tool calls, human corrections, or failure handling. Likewise, a run with higher compute cost can still pay off if it saves labor hours or measurably improves quality.
That is why the right unit of decision is the task or workflow, not the model in isolation. WorkLab also argues that the system around the model — data, context, tools, and process — shapes the value delivered. Microsoft WorkLab.
Before comparing costs, apply a risk filter
Not every task should immediately become a price contest between a human and an agent. Classify risk first. The greater the consequence of an error and the harder it is to detect or reverse it, the greater the human involvement should be.
- Impact of error: could a mistake change a financial, legal, medical, safety, people, or important external-communication decision?
- Reversibility: can the result be corrected before it creates a real-world effect?
- Verifiability: is there a clear and reasonably low-cost way to check whether the work is correct?
- Data and permissions: does the task involve sensitive information or systems that can take actions?
- Ambiguity: is the objective well specified, or does it depend on contextual judgment that is hard to turn into rules?
If risk is high and verification is difficult, the setup will often be human-led or hybrid, with explicit approval before external action. Microsoft’s 2026 Work Trend Index reinforces the need for evaluation infrastructure, quality standards, clear review ownership, and human accountability as agents execute more work. Source: 2026 Work Trend Index.
The framework: minimum quality, total time, and total cost
The order matters: quality and risk are constraints; time and cost choose among the options that pass those constraints.
1. Define “good enough” before testing
Build a set of representative cases and objective criteria. For analysis, criteria might include accuracy, coverage, source traceability, and absence of contradictions. For customer service, correct resolution, policy adherence, tone, and escalation. For code, tests, security, and maintainability.
Microsoft describes a similar approach through “eval sets”: evaluation sets that make explicit what good work looks like — accuracy, structure, reasoning, completeness, compliance, speed, or style. Source: Microsoft AI at Work.
Instead of asking only “did the agent get it right?”, track the pass rate without material rework, the severity of errors, and the effort required to fix failures.
2. Measure end-to-end time
Do not compare “model response time” with “human work time.” For AI, include context preparation, execution, tool calls, queues, retries, review, and correction. For humans, include preparation, execution, information retrieval, review, and dependency waits.
Track two numbers: elapsed time until the result is ready and human time consumed. An agent may run for 30 minutes in the background while using five minutes of human supervision; another workflow may return in seconds but require half an hour of checking.
3. Calculate total cost, not just token cost
Total cost per task = execution + tools/infrastructure + human preparation and review time + expected rework + expected failure cost.
For human execution, the main component is labor time. For agents, include tokens, model calls, tools, storage, integrations, and observability. For hybrid work, combine both sides. Expected failure cost can be approximated as failure probability × average impact.
| Mode | What to measure | Common trap |
|---|---|---|
| Human | Hours, loaded cost, quality, wait time, rework | Ignoring queues and opportunity cost |
| Agent | Tokens, calls, tools, latency, pass rate, retries, failures | Looking only at token price |
| Hybrid | Agent cost + review + corrections + final quality | Treating human review as “free” |
Decision rule: eliminate what does not meet minimum quality first
After testing, remove any option that falls below the quality standard or breaches the risk threshold, even if it is cheap. Among approved alternatives, compare total cost and time.
Avoid turning quality, time, and cost into a “magic score” without explicit weights. If the organization wants one index, weights should reflect the value of the work. In financial reconciliation, quality may matter more than minutes saved; in reversible internal triage, speed and cost may carry more weight.
Illustrative example: summarizing 100 records per week
Consider a hypothetical process for summarizing 100 feedback records each week. The team requires at least 90% of summaries to pass evaluation without material correction.
| Option | Pass without material correction | Elapsed time | Cost index (human = 100) | Decision |
|---|---|---|---|---|
| Human | 96% | 6 hours | 100 | Pass |
| Agent without review | 82% | 45 minutes | 18 | Fail |
| Agent + human review | 95% | 1 hour 45 minutes | 38 | Pass |
The numbers are only a method example, not market benchmarks. The agent-only option does not win simply because it is faster and cheaper: it is removed because it misses the defined standard. The hybrid option becomes comparable to human execution because it preserves quality within the risk limit while using less time and cost in this hypothetical scenario.
When human, agent, and hybrid modes tend to make sense
Agents become more attractive for repetitive, frequent, well-specified, measurable, reversible tasks with structured data access. The higher the volume, the more likely integration and evaluation investments can be spread across many runs.
Hybrid models are useful when AI can perform the high-volume part of the work but judgment, approval, exceptions, or relationship management still matter. They also provide a bridge while a team builds confidence and performance data.
Human execution remains especially relevant when volume is low, the task changes constantly, automation cost is high, quality is hard to evaluate, or the consequences require responsibility and context that should not be delegated.
Token budgets: manage by workflow and by run
If tokens are treated as operating capacity, spending must be attributable. The question becomes not only “how much did we spend on AI this month?” but also “which workflow consumed it, and for what outcome?”.
In August 2026, Microsoft engineers described a practical issue: a single agentic run can trigger many model calls and accumulate cost through retries, loops, and sub-agents. Their article recommends tracking cost at the run level rather than relying only on a monthly cap. Source: Microsoft Command Line — TokenOps.
- tokens and direct cost per run;
- number of calls and retries;
- human supervision time;
- first-pass acceptance rate;
- rework by error category;
- incidents or actions blocked by controls;
- cost per accepted outcome, not only cost per attempt.
Reassess whenever the economics or process changes
The decision is not permanent. WorkLab’s tokenomics argument notes that models and systems are becoming better, faster, and more efficient, so today’s cost may not represent next quarter. Source: Microsoft WorkLab.
Retest when there is a meaningful change in price, model, prompt, integration, policy, volume, required quality, or error cost. For important workflows, monthly or quarterly review can be more useful than a fixed annual choice.
Checklist before delegating
- Define the task and expected result in observable terms.
- Classify risk, reversibility, and the need for human approval.
- Create a representative evaluation set and a minimum quality standard.
- Test human, agent, and hybrid modes when all three are plausible.
- Measure elapsed time and human time consumed.
- Calculate total cost, including review, infrastructure, rework, and failures.
- Eliminate options that fail minimum quality or safety requirements.
- Among the remaining options, compare cost, time, and operating capacity.
- Set budget and observability by workflow or run.
- Reassess when models, prices, or work conditions change.
Tokenomics at work is less about buying “cheap tokens” and more about creating an allocation discipline. The right setup delivers the required quality, within acceptable risk, at the lowest end-to-end cost and time for that specific task — and keeps being measured after deployment.