Changing two sentences in a prompt and liking the next answer better does not prove that the prompt has improved. The case may have changed, the model may have varied the output, or the new version may have been better at one type of task and worse at another. The useful question, therefore, is not “is this answer good?”, but “does the new version beat the old one repeatably in the cases that matter, without creating relevant regressions?”.
This reasoning brings the evaluation of prompts closer to a test. OpenAI's evaluation documentation recommends explicit objectives, datasets tied to real-world usage, defined metrics, and continuous comparison. Anthropic also starts from measurable success criteria, cases close to real distribution and clear rubrics. Google Cloud, in turn, documents pairwise evaluation as an appropriate way to choose between prompts when the goal is to compare two alternatives. The common idea is simple: first define what counts as success; then generate evidence.
The most common mistake: changing the prompt and changing the test at the same time
Imagine that version A responded poorly to a complicated request. You rewrite the prompt, send another simpler example, and version B responds better. This may be a sign of progress, but it is not a comparison. To measure the effect of the change, the input case needs to be the same, and the other relevant variables need to remain controlled as much as possible.
If the goal is to test just the prompt, keep the same model and model version, the same system instructions, the same available tools, the same retrieved context, the same output size policy, and equivalent generation parameters. When any of these conditions need to change, record the change. Without this, an improvement may be being attributed to the prompt when it came from another part of the system.
In manual use, the control does not need to become an academic laboratory. Just write down what was kept fixed and run A and B on the same set of cases. The important thing is that the comparison has stable rules.
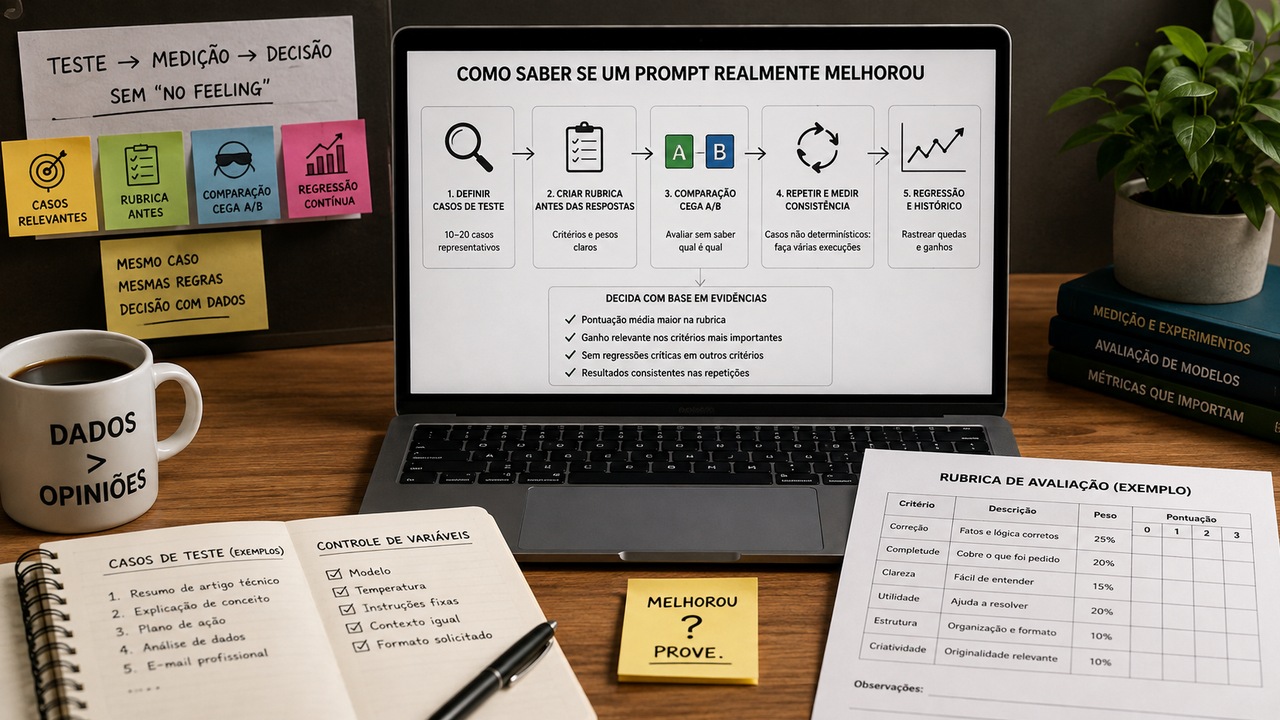
Start with 10 to 20 cases that represent real work
For a first operational evaluation, a set of 10 to 20 cases may be enough to discover large differences between two versions. This number is not a universal statistical standard nor does it guarantee that a prompt is ready for any use. It serves as a high-utility starter set, small enough to review manually and large enough not to rely on a single example.
The cases must cover the center and edges of the task. If the prompt summarizes documents, don't just test short, well-written texts; include long material, missing information, contradictory passages, and entries with irrelevant details. If the prompt responds to customers, include a common request, an ambiguous message, an out-of-policy request, an angry customer, and a case where the correct response is to admit that information is missing.
It is useful to separate cases by slices. One slice may be “simple request”, another “ambiguity”, another “risk of inventing information”, another “formatting”. When the final average changes, these slices show where the gain happened and where a regression was hidden.
It is also worth reserving some cases that will not be used when rewriting the prompt. They function as a small validation outside of the set that guided the improvement. This reduces the risk of adjusting version B only for the examples you already know.
Set the rubric before looking at the answers
A rubric turns “I liked it most” into observable criteria. The timing of writing it matters: if the criteria appear after you've already seen A and B, there's a temptation to choose rules that favor the preferred answer. Therefore, write the rubric before generating or comparing outputs.
For a general text assignment, a rubric may combine correctness, adherence to instruction, completeness, clarity, and format. There is no universal combination. The rubric should reflect what would cause success or failure in actual use. If omitting a critical caveat is worse than writing less elegantly, this weight needs to appear in the evaluation.
A short scale is usually easier to apply consistently. For example, each criterion can be scored from 0 to 3. Zero means serious failure or absence of the requirement; 1 means partial service with relevant problem; 2 means adequate service with minor flaws; 3 means complete service. The value of the scale is less in the number and more in the anchors that explain what each note means.
Weights may reflect priority. In a customer response prompt, a plausible example would be correctness at 30%, adherence to instruction at 25%, completeness at 20%, clarity at 15%, and format at 10%. If a dimension is non-negotiable, also treat it as a blocking criterion. Thus, a version is not approved just because it compensated for a critical flaw with good writing on other items.
Compare A and B without letting the version name contaminate the judgment
A simple blind comparison helps when the evaluation is human. Instead of showing “old prompt” and “improved prompt,” label the answers as X and Y, shuffle the order in each case, and ask the evaluator to apply the rubric without knowing which version produced each output. Then, reveal the origin.
This design is especially useful when the person evaluating it also wrote the new version. The person naturally expects the change to work. Hiding the identity of responses does not eliminate all biases, but it reduces the chance of turning expectations into scores.
In addition to the grade per rubric, record the direct preference: X best, Y best or tie. Pairwise evaluations are useful when two answers are acceptable, but one better meets the objective. OpenAI's own documentation highlights that models tend to be more reliable when discriminating options than in fully open evaluations, and Google Cloud offers pairwise metrics specifically for comparing prompts and models.
Repeat the cases where the output varies
Generative models can produce different answers for the same input. A single execution can favor A or B by chance. If an important case fluctuates, run both versions again keeping the configuration the same.
In a manual process, three repetitions can already reveal a useful pattern: a version that looked excellent in the first round may fail in the next two, while another may be less brilliant but more stable. For tasks with higher risk or greater variability, increase the number of repetitions and treat stability as a criterion in its own right.
Do not add repetitions as if they were independent cases without thinking about the design. The practical goal is to find out if the behavior is consistent. Record each run and then summarize the trend by case: A stable win, B stable win, draw or volatile result.
Regression is the part that the average hides
A new version could raise the average score and be even worse. This happens when she improves many easy cases, but breaks a rare and important case. Regression is precisely the loss of performance in something that previously worked.
Therefore, compare case by case. Mark as regression any situation in which B got worse compared to A and rate the severity. A small drop in style may be tolerable; inventing information that the previous version did not invent can block the change.
Before testing, define the decision rule. A practical example would be: B needs to have a higher weighted score, win more cases than he loses and not show critical regression. Another project may require a minimum gain in a specific criterion, such as format adherence. The important thing is to avoid creating the rule after seeing the score.
The model spreadsheet can be simple
You don't need an evals platform to get started. A spreadsheet already allows you to execute a disciplined process. Each line represents a case or a repetition of a case. Essential columns can be: Case ID, Slice, Input, Expected Behavior, Criticality, Rated Version, Replay Number, Response, Grades by Criterion, Weighted Grade, A/B Preference, Regression, Observation, Model and Configuration Used.
If you want to keep A and B side by side, use one row per case with two blocks of columns: answer A and grades A, answer B and grades B. Add a “winner” column and another “critical regression?” For blind comparison, evaluate first on a copy where the answers appear as X and Y; only then fill in the column that reveals which prompt generated each one.
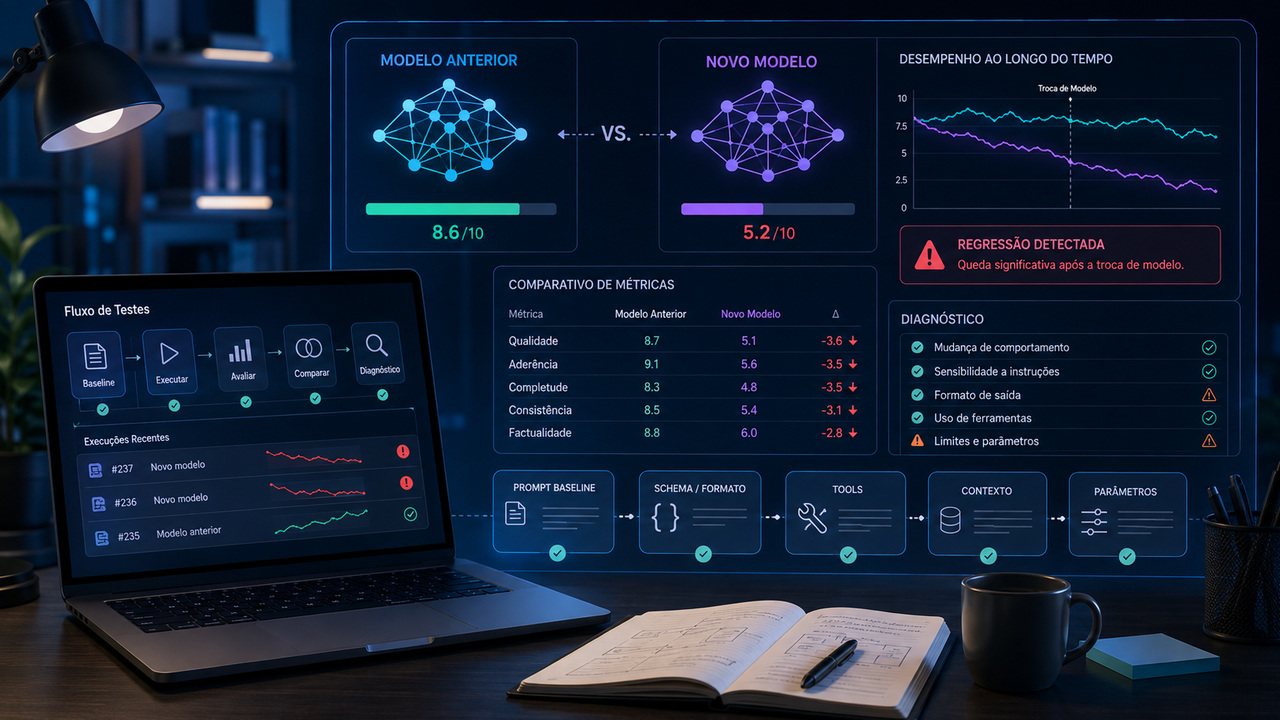
The spreadsheet must also save the exact version of the prompts. Avoid vague names like “new prompt”. Use identifiers such as A-2026-08-16 and B-2026-08-16. If the assessment is repeated in the future after changing the model, context, or tool, this history helps distinguish regression from prompting changes in the rest of the system.
Complete example: from a generic prompt to a testable prompt
Consider a fictional case: a team uses AI to answer customer emails about the progress of requests. Version A of the prompt says: “Respond to the customer politely and objectively, explaining the status and next step.” Sounds reasonable, but leaves important decisions implicit.
Version B says: "Respond to the customer in up to 120 words. Explain only information present in the context provided. Inform current status, confirmed next step and, if there is no confirmed deadline, explicitly state that the deadline is not yet available. Do not invent dates, responsible parties or guarantees. Maintain a cordial and direct tone."
Before testing, the team defines four criteria. Factual correction receives 35% weight; adherence to restrictions, 30%; completeness, 20%; clarity, 15%. Inventing a deadline or person responsible is a critical regression and blocks approval, regardless of the average.
The set contains 12 cases. There are simple messages, orders without a confirmed deadline, angry customers, incomplete context and a case in which the history shows two conflicting dates. Responses are generated with the same model, the same configuration and the same context for each case. An evaluator only receives X and Y, without knowing which corresponds to A or B.
Suppose that, in this hypothetical example, B wins 8 cases, A wins 2 and there are 2 draws. B also obtains a higher weighted average. However, in a case with conflicting dates, B chooses a date and presents it as confirmed, while A avoids stating a deadline. According to the rule defined before the test, B is not yet approved: there has been a critical regression.
The team then changes only the statement related to information conflict, creating a C version. The same 12 cases are repeated, paying special attention to the case that failed. If C maintains B's gains and eliminates the critical regression, there is much stronger evidence of improvement than the impression made by a pretty answer.
The point of the example is not that every test needs 12 cases, four criteria, or those weights. The point is that the decision was decided before the score, the versions faced the same entries and an average improvement did not erase an important flaw.
How to choose between absolute grade and A/B preference
The absolute score answers “how well does this answer meet the standard?”. It is best when the team needs to know whether each version passes a minimum level. The A/B preference answers “which of the two is better in this case?”. It is useful when answers are difficult to score accurately, but the difference between them is noticeable.
The two approaches can coexist. Use the rubric to check minimum quality and critical criteria; use the pairwise preference to compare versions directly. When rubric and preference disagree, investigate the case rather than hiding the divergence in the mean.
Automatic evaluation can also be included in the process. Code rules are great for objective requirements such as presence of fields, valid format, or maximum size. Human judgment is more flexible, but it costs time. A judging model can scale subjective assessments, but it needs to be tested and calibrated against human assessments before receiving operational confidence. Anthropic and Google Cloud documentation explicitly address this need for clear rubrics and automatic grader calibration.
When a prompt can be considered better
A change is well supported when there is convergence of evidence: the new version improves the main metric, wins more relevant cases, maintains or improves priority criteria, does not create critical regressions and repeats the result in cases that present variability.
This is different from demanding perfection. Real prompts almost always involve trade-offs. A version might be a little longer and, in turn, reduce omissions. Another may gain clarity but lose speed. Testing makes this cost visible so the team can choose consciously.
It is also healthy to record an inconclusive result. If A and B are tied, if repetitions fluctuate a lot or if the rubric cannot separate quality, the correct conclusion may be “there is still no evidence of improvement”. This is better than forcing a victory to justify the work already done.
Turn new failures into permanent cases
The test suite must not be frozen. Whenever a real major failure arises, turn it into a new regression case. At the next prompt change, this case is executed again. Over time, the suite comes to represent not only planned examples, but also errors that the system has already made.
This cycle is what makes prompt evaluation stop being an occasional review and become quality control. The new version doesn't just have to sound intelligent in conversation; it needs to survive the history of problems that the team has already learned to recognize.
In the end, “better prompt” is a comparative statement. It only makes sense when there is a reference version, a set of cases, criteria defined before observation and a decision rule. Feeling remains useful for formulating hypotheses and realizing that something could be better. Approval, however, must come from testing.