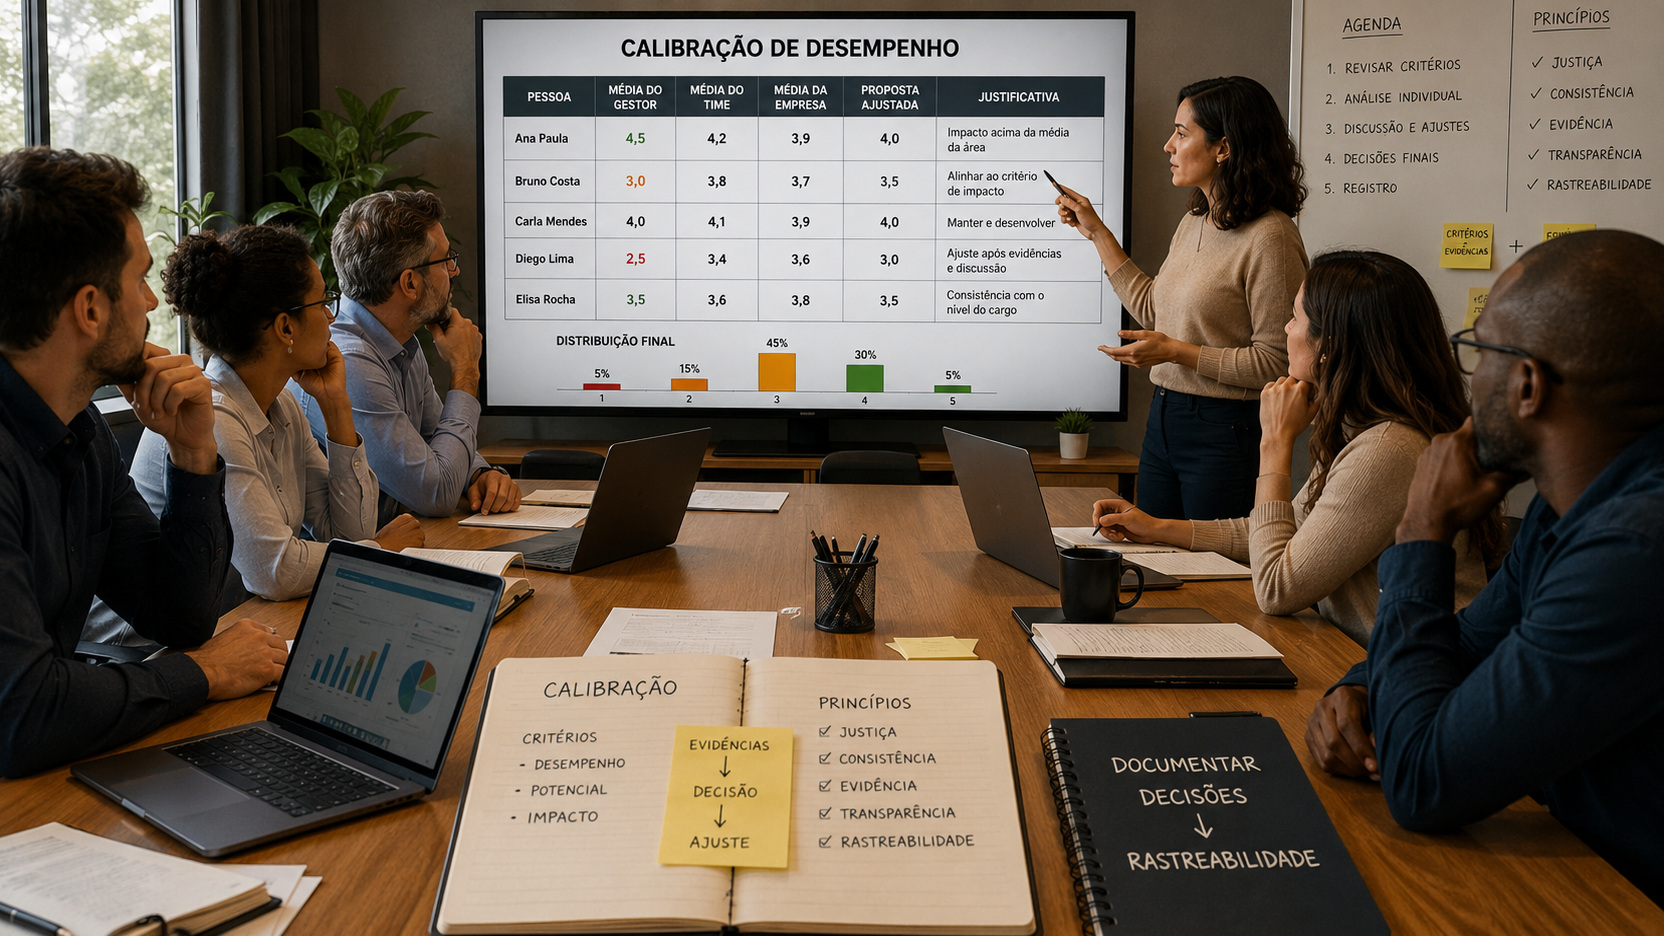
A calibration meeting is meant to test whether different managers are applying the same performance standard in a comparable way. It can change ratings, but the goal should not be to produce a neat statistical shape or force every department into the same distribution. A well-run calibration starts with the criteria, moves through the evidence, and ends with a documented decision. The distribution of ratings is a signal to investigate, not a target to obey.
That distinction matters because research on calibration itself presents a more complicated picture than the promise of "greater fairness." There is evidence that discussion among managers can increase information and consistency, but also that the committee can compress ratings, favor those who are better able to defend their cases, and reproduce power asymmetries. The design of the meeting therefore needs to be as careful as the rating scale.
What calibration should correct - and what it should not try to manufacture
Calibration means comparing how the criteria are being applied. If two professionals at the same level delivered equivalent results in comparable contexts, a large difference in rating calls for an explanation. Perhaps the contexts really are different. Perhaps one manager is using a stricter standard. Perhaps relevant evidence was left out of the review. The meeting exists to make those differences examinable.
That is different from starting with a desired curve and adjusting people until the percentages match. A distribution can reveal that a team is clustering ratings very high or very low, but the histogram does not prove by itself that the ratings are wrong. When the facilitator first asks, "who are we going to lower to make the band work?", the logic has already changed: the process has stopped testing criteria and started pursuing a quota.
Research by B. William Demeré, Karen Sedatole, and Alexander Woods, published in Management Science, helps explain the risk. In the setting they studied, calibration committees increased consistency across supervisors and reduced leniency bias, but they also worsened centrality bias, meaning the tendency to compress evaluations around the middle of the scale. The finding is a warning against treating convergence as an automatic synonym for quality.
The evidence also shows why calibration can be worthwhile
In 2019, Andrew B. Speer, Andrew P. Tenbrink, and Michael G. Schwendeman published two field studies on calibration meetings in Human Performance. The authors found associations between participation in calibration and a greater perception of a common evaluation reference point, greater manager accountability, and a larger amount of information available for forming ratings. In the second study, post-calibration ratings were also more strongly correlated with other measures from the performance domain than the pre-calibration ratings.
That does not mean every calibration meeting improves every system. It means that a structured conversation can add information and align reference points. The mechanism is plausible: a manager stops evaluating only within their own team and must explain their interpretation to other managers, hear comparable cases, and answer questions that might not arise in an individual review.
The counterpoint became more explicit in a 2025 article by Jasmijn C. Bol, Andson Braga de Aguiar, and Jeremy B. Lill in Human Resource Management. Using data from 737 employees and 114 supervisors in one organization, the authors found evidence consistent with strategic information sharing by supervisors. They also observed differences in whose ratings were adjusted: supervisors with a lower cost of avoiding scrutiny and defending their ratings received fewer adjustments and ended with higher ratings, even after controlling for employee performance. The practical message is clear: calibration does not eliminate organizational politics simply because more people are in the room.
Before the meeting, freeze the first evaluation
The first control is simple: each manager should finish and record their preliminary ratings before seeing the group discussion. The Equality Action Center, in the Bias Interrupters toolkit, recommends this kind of precommitment precisely to reduce the influence of the first position that dominates the room. Without a frozen initial version, it becomes difficult to know what changed, why it changed, and whether the change resulted from new evidence or social conformity.
The prior record also creates the basis for traceability. For every person evaluated, the process should be able to recover the initial rating, the final rating, the criteria that supported the decision, and the rationale for any change. If the company uses a performance management system, this trail should remain accessible for internal audit of the cycle.
Define the standard before comparing people
A calibration meeting is not the best place to discover what the scale means. Before the session, HR and leadership need operational definitions for each rating and
examples of evidence compatible with each level. Terms such as "exceeded expectations" or "exceptional" are useful only if there is a shared understanding of which results, behaviors, and impacts justify the classification.
UC Davis, in its calibration guidance, recommends anchoring ratings in observed results and behaviors and considering the effective review period. The material also separates the rating process from financial merit decisions. That separation is useful even outside that context: if budget, bonuses, or headcount put pressure on the meeting, the rating can become a tool for solving a constraint that did not originate in the performance review.
The criteria also need to allow fair comparison. Putting people with very different levels, functions, or scopes into the same contest creates false precision. When the organization needs to calibrate a large population, it is better to structure the discussion around groups that are sufficiently comparable and to make scope differences explicit when a case crosses boundaries.
Bring evidence, not adjectives
For every rating under discussion, the manager should be able to answer three questions: what happened, what the impact was, and why that corresponds to the proposed level on the scale. The quality of the meeting improves when the language moves away from labels such as "brilliant," "difficult," "not very strategic," or "lacks presence" and toward facts from the review period.
That does not eliminate judgment. Performance evaluation has subjective components, especially when it involves collaboration, leadership, decision quality, or impact that is difficult to reduce to a metric. The point is to make the judgment examinable. If someone says a person "does not demonstrate leadership," the meeting should ask for examples, context, and a connection to the defined competency. If the comment does not change how the criterion should be interpreted, it should not change the rating.
The Bias Interrupters toolkit moves in that direction by recommending a consistent rubric and active intervention when the conversation drifts away from the criteria. In practice, the facilitator does not need to accuse anyone of bias to do this. It is enough to ask: "what evidence from the review period supports this difference?", "are we applying the same standard we used in the previous case?", or "does this point belong in the rubric?"
Run the meeting around meaningful disagreements, not every name
If every case receives the same amount of time, the meeting can become long without becoming more rigorous. Preparation can be used to locate where there is real uncertainty: ratings that are far from the distribution of the comparable group, disagreement between evidence and rating, a large change from previous cycles without explanation, extreme ratings, or managers whose standards appear systematically higher or lower.
The caution is not to turn those signals into automatic condemnation. A team can legitimately have several very strong performers. A manager may have taken over a mature and exceptional unit. A rating change may reflect a real increase in scope. The
signal is there to decide where to ask questions, not to determine the answer.
Start the discussion with the standard
Before opening a case, the facilitator reminds the group which competency or dimension is at issue and what distinguishes the relevant levels. That reduces the chance that the group changes the meaning of the scale from person to person.
Listen first to the person with the closest evidence
Hierarchy in the room is not the same as better information. The study by Demeré, Sedatole, and Woods found that committees tended to defer more to the supervisor's decision when that supervisor had a greater informational advantage about the subordinate than the committee members did. The principle is useful: challenging the direct manager is part of calibration, but replacing that manager's judgment with authority that lacks evidence can make the decision worse.
Require the same standard for moving a rating up or down
A rating should not require documentation only when it is high. Reductions also need a basis. If a disagreement ends in an adjustment, the group should be able to identify which evidence changed the interpretation and which criterion is being applied more accurately after the discussion.
How to resolve disagreement without letting rank win
The worst dynamic is a decision made by volume of voice or seniority. To prevent that, the meeting needs a decision rule that is known before the difficult cases begin. In some organizations, the direct manager keeps the decision unless there is robust new evidence. In others, the committee decides by consensus or through a designated final authority. Any model can be used, but the final decision-maker and the method for recording disagreements need to be explicit.
When there is an impasse, the facilitator can separate three situations. The first is missing information: the case goes back for evidence gathering and should not be resolved by guesswork. The second is disagreement about the criterion: the group needs to correct its interpretation of the standard before deciding the person's rating. The third is different judgment even with clear facts and criteria: in that case, the decision rule is applied and the rationale is recorded.
Recording dissent matters because apparent consensus can hide conformity. A final rating can be valid even without unanimity, as long as the organization knows who decided, with what information, and under which criterion.
Treat the distribution chart as a diagnostic, not a quota
Showing the distribution before and after calibration can be useful. It makes it possible to see compression, leniency, severity, and differences across managers. But the right question is "what explains this pattern?", not "how many people do we need to move?"
One practical safeguard is to prohibit adjustments whose only rationale is the distribution. If a rating changes, the record needs to cite evidence and criteria. The sentence "we already have too many people at 4" is not performance evidence. If the company has a separate forced-distribution policy, that policy should be named as
such; it should not be hidden inside a meeting presented as calibration of criteria.
It is also useful to look at the direction of adjustments. If nearly every change pushes ratings toward the center, the process may be producing centrality. If one manager has almost all ratings reduced while another almost never has a rating changed, there is a difference worth diagnosing. Those patterns do not prove error, but they indicate where to review process consistency.
Document each adjustment so someone else can reconstruct the decision
Traceability is not a transcript of everything that was said. It is a minimum record that makes it possible to answer later: what was the initial rating, what was the final rating, was there a change, which criterion was decisive, which evidence supported the adjustment, and who had authority to close the case.
It is also worth recording when an issue remained pending for lack of evidence. That prevents time pressure in the meeting from turning missing information into a definitive rating. If later information changes the case, the history shows why it was reopened and who approved the change.
For HR, the decision log enables a process review without reopening every evaluation. It is possible to see which criteria generated the most disagreement, which managers had the most adjustments, in which direction ratings moved, and where the rubric needs better examples in the next cycle.
Check patterns afterward without using identity as a shortcut in individual decisions
An organization that tracks quality and equity can analyze aggregated patterns after calibration, while respecting its data governance and applicable rules. The goal is to look for asymmetries that deserve investigation, not to use membership in a group as a substitute for evidence about individual performance.
The Equality Action Center recommends looking at both quantitative data and language patterns in evaluations. The value of that check is that it can detect problems that do not appear in a single case. If some groups systematically receive personality comments while others receive comments about results and leadership, for example, the organization gains a signal to review rubrics, training, and facilitation.
After the meeting, the manager needs to stand behind the final decision
Calibration should not produce the script "I gave one rating, but the committee took it away." For the employee, the final evaluation is an organizational decision and needs to be explained using the same criteria and evidence used to close it. When the manager shifts responsibility to an invisible room, traceability may exist internally, but the credibility of the feedback drops.
The lessons from the cycle should also be retained. If managers interpreted one competency in three different ways, the problem does not end when the ratings are finalized. The next version of the rubric needs a better definition, examples, or training.
Good calibration improves not only that year's ratings, but also managers' ability to evaluate in the next cycle.
A concise agenda for the session
The meeting can begin by confirming scope, scale, comparable groups, and the decision rule. Next, the facilitator quickly reviews the criteria that generated the most uncertainty during preparation. Preliminary ratings should already be recorded before the discussion.
Then come the cases selected for disagreement or inconsistency risk. The manager presents evidence and the connection to the rubric; the others ask questions using the same standard. Any proposed adjustment needs to state which fact or interpretation changed. If information is missing, the case leaves the meeting as pending, with an owner and deadline, instead of being decided under time pressure.
At the close, HR confirms the final ratings, the adjustments and their rationales, reviews whether the distribution was improperly used as a quota, and records systemic issues for the next cycle. Calibration ends when the decisions can be reconstructed and defended by the criteria - not when the chart becomes symmetrical.