Prompt caching works best when you treat the beginning of the prompt as a stable interface, not as a document that can be reassembled with each call. The central idea is simple: if several requests start with a reusable prefix, the provider can reuse work already done in processing that segment. If something changes too soon, the common stretch shrinks and some of the benefit disappears.
This explains behavior that often seems contradictory. Two prompts can be virtually the same for one person and still not leverage the same cache. The mechanism does not ask whether the texts have the same meaning. It works with the structure actually sent to the model, respecting prefix rules, minimum limits, cache points, lifetime and availability defined by each provider.
What prompt caching actually reuses
Before generating the response, the model needs to process the input context. In this step, called prefill, the system calculates internal representations used by the attention mechanism. Prompt caching services turn some of this work into a reusable resource between calls that share a compatible prefix.
This is different from application memory. The cache does not replace database, persistent history, RAG, session state, or agent memory. You remain responsible for submitting or referencing the content required for the assignment. The gain comes from avoiding repeated processing of a part that the provider has already seen and can recognize as reusable.
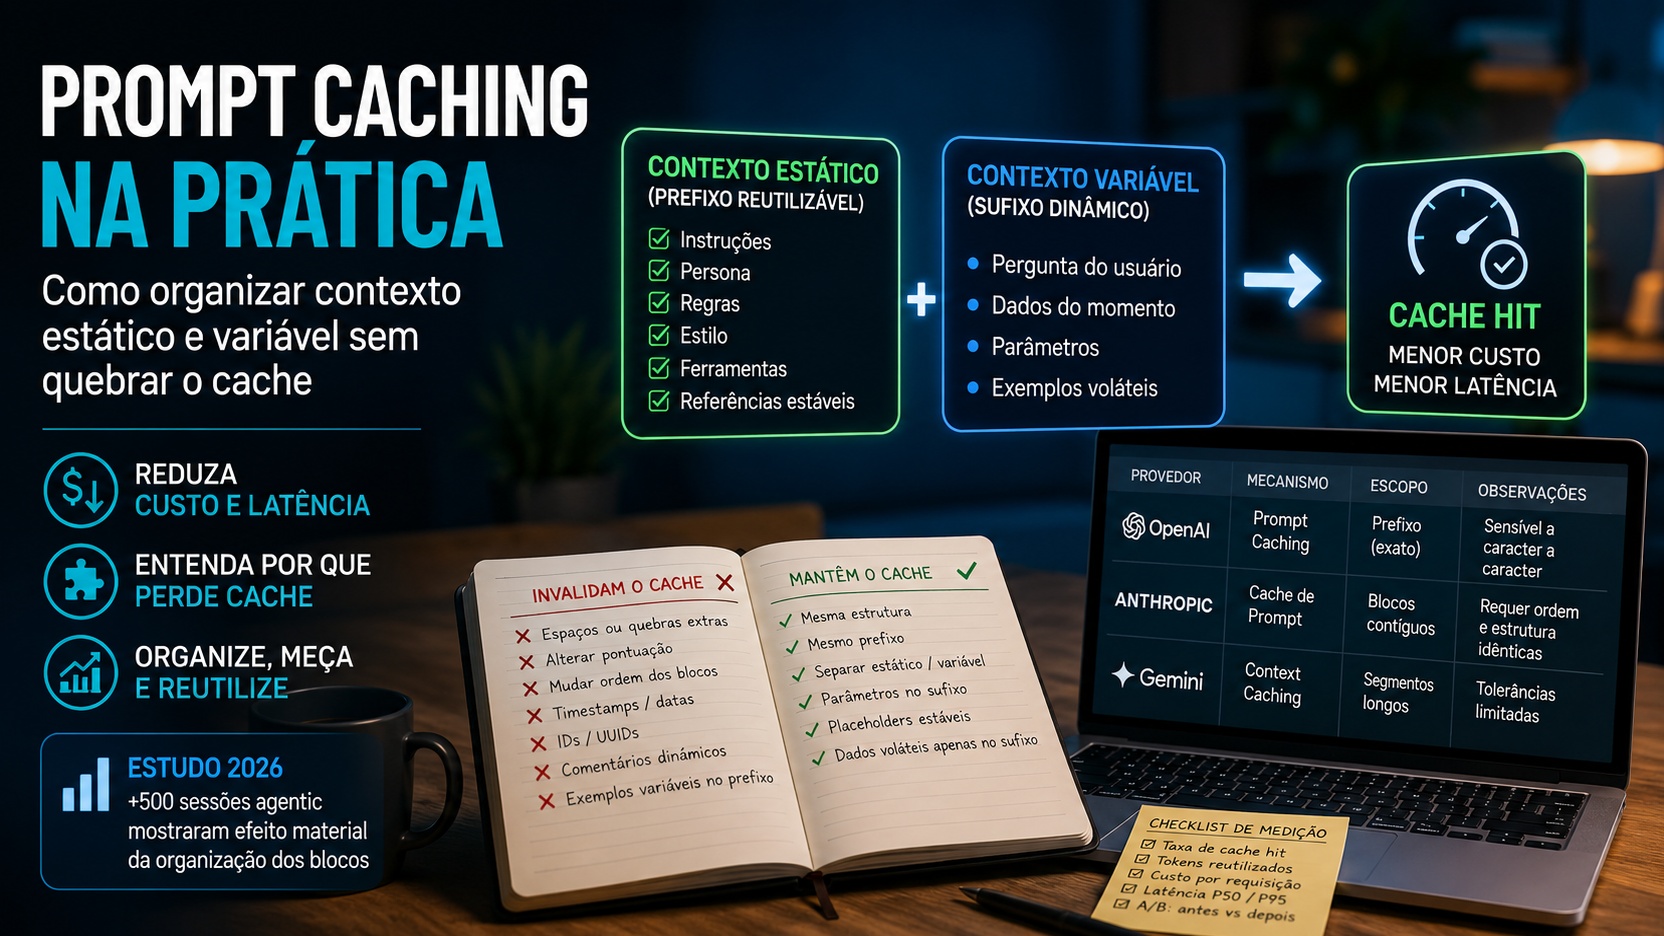
In practice, think of a prompt as two regions. The first contains what changes little: system instructions, policies, examples, tool definitions, schemas and stable references. The second focuses on what changes with each execution: user question, identifiers, timestamp, data retrieved at that moment, tool results and specific parameters.
request.
The earlier the variable part appears, the smaller the prefix that can be reused tends to be. The more stable and longer the initial prefix, the greater the caching opportunity, as long as it exceeds the minimum threshold and remains within the provider's rules.
The rule of thumb: static prefix first, variable data second
The most robust organization starts with the content that multiple requests actually share. Standing instructions, business rules, output formats, stable few-shot examples, tool descriptions, and reused reference material belong at the beginning. Per-user or per-execution content must go after the reusable boundary.
This border does not need to be an abstract concept. In APIs that offer explicit breakpoints, it can be marked directly. In automatic mechanisms, you can still structure the prompt so that the repeated prefix is identical and sufficiently long before it starts to vary.
It is also worth separating operational data that does not need to be in context. A request ID used only for logs, for example, should not occupy a position in the static prefix if the API offers metadata for this purpose. The same goes for timestamps placed in the prompt for convenience but with no real function in the response.
Before and after: the same agent with different structures
Before: prompt changes before getting to the reusable part
Imagine an agent that assembles each call in this order: current timestamp, request ID, user profile, list of tools enabled at that moment, general instructions, examples and, finally, the question. The system can even repeat almost the entire text, but the first blocks change with each execution. Visual similarity is high; the reusable prefix does not.
If the application still serializes the tool schemas in a different order between calls, the problem increases. Changing the order of tools, properties or blocks within the cacheable region can generate a different prefix even when the intention is the same.
After: the prefix is deliberately stable
A more cache-friendly version starts with stable system instructions, policies, tools in deterministic order, schemas, examples, and reference context that actually repeat. Then comes the curly border. Only then do the user's specific profile, question, IDs, timestamp and data recovered in that execution enter.
The change seems just editorial, but it is architectural. You fail to ask “is this prompt similar to the previous one?” and goes on to ask “what is the largest identical prefix worth reusing?”. This second question is much closer to the way mechanisms are documented.
Which breaks the cache without seeming like a big change
Small changes within the prefix
In OpenAI, current documentation requires exact prefix matching for cache hits. Therefore, changes to content, order, images, tools or schemas before the relevant boundary can reduce reuse. Spaces, line breaks and punctuation can also matter when they change the tokenization of the section that should remain stable.
In Claude, the cache is calculated based on the prefix formed by tools, system and messages up to the breakpoint. The documentation itself warns that changes to blocks prior to the cache point
produce another hash. It also recommends keeping the ordering of keys in tool use blocks stable, because non-deterministic serialization can break reuse.
The lesson is not to freeze the entire application. It's making the part you expect to reuse deterministic.
Tools and schemas that change per request
Tool definitions tend to be large and therefore seem like natural candidates for caching. The problem arises when the application creates a different list for each call. Adding, removing, reordering or rewriting tool descriptions within the prefix may reduce hits.
An alternative is to keep the base definition stable and control availability through API-specific mechanisms when they exist. In OpenAI, for example, the documentation recommends leaving the tools array unchanged and using authorized_tools when supported, rather than rebuilding the list just to restrict the available subset.
History rewritten instead of just extended
In long conversations, a simple caching strategy is to preserve previous history and only append new messages. When the application rewrites old messages, reorders events, changes summaries or compresses previous sections, the prefix also changes.
Compression may still be a good decision to reduce total context. The point is that it has an opportunity cost: a smaller context may be cheaper, but the rewrite may reset a region that was being reused. The correct decision depends on measuring both, and not assuming that fewer tokens sent always means lower effective cost.
TTL, minimum limit and availability
Not every cache miss is a consequence of a change in the prompt. Providers impose minimum sizes and lifetimes. Some mechanisms are also best-effort: the content can remain identical and, even so, there is no entry available in the infrastructure that responds to that call.
Therefore, “the prompt is the same” is not sufficient as a diagnosis. You need to know if the prefix has reached the minimum, if the entry is still alive, if there was a previous write to the right point, and if the API reported tokens actually read from the cache.
OpenAI, Claude and Gemini: same idea, different controls
The three ecosystems converge on the importance of common content at the beginning, but they do not expose exactly the same interface. Treating everyone as if they had the same policy tends to lead to fragile configurations.
OpenAI
The OpenAI documentation describes automatic prompt caching for eligible requests and emphasizes that cache hits depend on exact prefixes. For GPT-5.6 and later families, the minimum cacheable is 1024 tokens and the API also offers explicit breakpoints in addition to implicit mode.
In these newer models, a breakpoint marks the end of the reusable prefix. The content after it may vary without invalidating the previous prefix. The documentation also recommends using a consistent prompt_cache_key to improve matching between related calls. To measure results, cached_tokens shows cache reading; In GPT-5.6 and later, cache_write_tokens helps you see when the application is writing too much and reusing too little.
Previous models maintain automatic behavior with minimum limits that vary by model. The practical implication is not to code a single size rule for the entire fleet without checking the model actually used.
Claude
In Claude, the developer can use cache_control in automatic mode or place explicit breakpoints in individual blocks. The prefix follows the order tools, system and messages. The documentation recommends placing static content at the beginning and marking the end of the region that remains identical between calls.
The default TTL is five minutes, with an option for one hour under another pricing structure. Minimum sizes also vary by model. To diagnose, the response separates cache creation and read tokens, which allows you to distinguish a call that wrote an entry from one that actually reused it.
An important detail is that Claude performs block lookback when searching for previously written entries, but this does not transform unstable content into stable content. If the breakpoint is placed on a block that changes with each request and there is no suitable previous entry, the application will continue to create new prefixes instead of reusing what was intended.
Gemini
In Gemini, implicit caching is enabled by default on Gemini 2.5 and later models. The documentation recommends placing large, common content at the beginning and sending requests with similar prefixes in a short interval. Minimum limits depend on the model: in documentation consulted in August 2026, Gemini 2.5 models list a minimum of 2,048 tokens, while several 3.x families list 4,096.
GenerateContent also offers explicit caching in which the application creates a cache object and references it in later calls. In this mode, the default TTL is one hour if not configured, and the cost considers both cached tokens and storage time. The Interactions API only documents implicit caching.
For operation, this means that “Gemini has cache” does not answer which cache is being used. You need to distinguish the automatic mechanism from the explicit cache object and measure the tokens reported as reused in the usage metadata.
What the 2026 study adds to production testing
The preprint Don’t Break the Cache, by Elias Lumer and co-authors, evaluated prompt caching in more than 500 agent sessions on DeepResearch Bench, with system prompts for 10 thousand tokens, covering OpenAI, Anthropic and Google. The study compared full context caching, system prompt-only caching, and a strategy that excluded dynamic results from tools.
The most useful result is not a single percentage, but the difference between strategies. The authors found cost reductions of 41% to 80% in the models evaluated and showed that latency improvements vary more by provider and configuration. In one of the conditions, the naive full context cache actually worsened the time to the first token, because dynamic content generated writing work without proportional reuse.
The operational conclusion converges with the static prefix architecture: controlling the cache boundary was more consistent than trying to store everything. In the main study set, system prompt-only caching appeared as an especially stable strategy between cost and latency, although the absolute best configuration varied by model.
This type of benchmark does not replace your own measurement. The article itself highlights that TTFT suffers from variations in load, region and infrastructure. What it provides is a strong engineering hypothesis to test: before increasing TTL or trying to cache more blocks, remove volatile content from the reusable region.
How to measure whether the reorganization really worked
Cache hit request rate
Count how many calls return some volume of tokens read from the cache. This metric helps detect sudden regressions, but alone does not inform the magnitude of the benefit. A hit of a few tokens and a hit of tens of thousands appear equally as a “cached request”.
Proportion of tokens reused
Track how many input tokens were read from the cache relative to the volume of input that could be reused. This is a metric closer to the economic effect of the prefix design. If the rate of hit requests is high but the proportion of reused tokens is low, the frontier may be too early.
Relationship between writing and reading
When the API exposes create or write tokens, compare them with read tokens. An application that repeatedly writes cache and barely reads it is paying the maintenance cost without capturing the expected benefit. This pattern usually points to a poorly positioned breakpoint, TTL incompatible with the cadence or variable content within the written region.
Effective cost per request
Use the price of the model actually contracted and separate normal input, cache write, cache read and output when the provider makes this distinction. Don't just compare “total tokens”, because a token read from the cache may have a different price than a token processed from scratch.
TTFT in p50 and p95
Prompt caching primarily affects input processing, so time to first token is a more sensitive metric than total duration when output is long. Measure at least median and tail. A p50 improvement accompanied by strong p95 regression can be bad for an interactive application.
A/B before and after with the same load
Compare the old and new framework using the same request set, model, region, and concurrency pattern. Make warm-up calls when necessary, separate first write from subsequent reads, and do not mix prompt change with model change in the same experiment.
An architectural checklist that prevents most cache misses
Before blaming the provider, check whether the prefix really remains stable between requests. Instructions, examples, tools and schemas must have deterministic serialization. Per-user data, request IDs, timestamps, and tool results should appear after the reusable part whenever semantics allow.
Also confirm the minimum threshold of the model and the TTL of the engine used. Then validate the telemetry of the API itself: cache tokens read, tokens written when available, cost, and TTFT. If the system only records total tokens, it is difficult to distinguish a caching problem from a simple change in context size.
Finally, treat cache as an optimization, not as a functional requirement. A cache miss should not change the correct answer or break the agent's flow. The system needs to work without caching and be cheaper or faster when reuse happens.
The objective is not to curl everything; is to preserve what really repeats itself
Prompt caching rewards predictable architecture. The best prefix is not the longest possible, but the longest chunk that is simultaneously stable, frequently reused, and compatible with the model and API rules.
When cost or latency worsens, the first investigation should be structural: where does the first variable data appear? Are tools and schemas changing? Is ancient history rewritten? The breakpoint is after the right block? Does TTL cover actual cadence? Does telemetry show reading or just new writing?
Organizing static context first and variable context later turns these questions into measurable decisions. Instead of hoping the cache works, you design the prompt to produce a reusable prefix and can prove, with your own usage data, whether the optimization is paying off.