Category

Tests and Comparisons

Reproducible assessments by task, cost, speed, accuracy and ease of use.

20articles
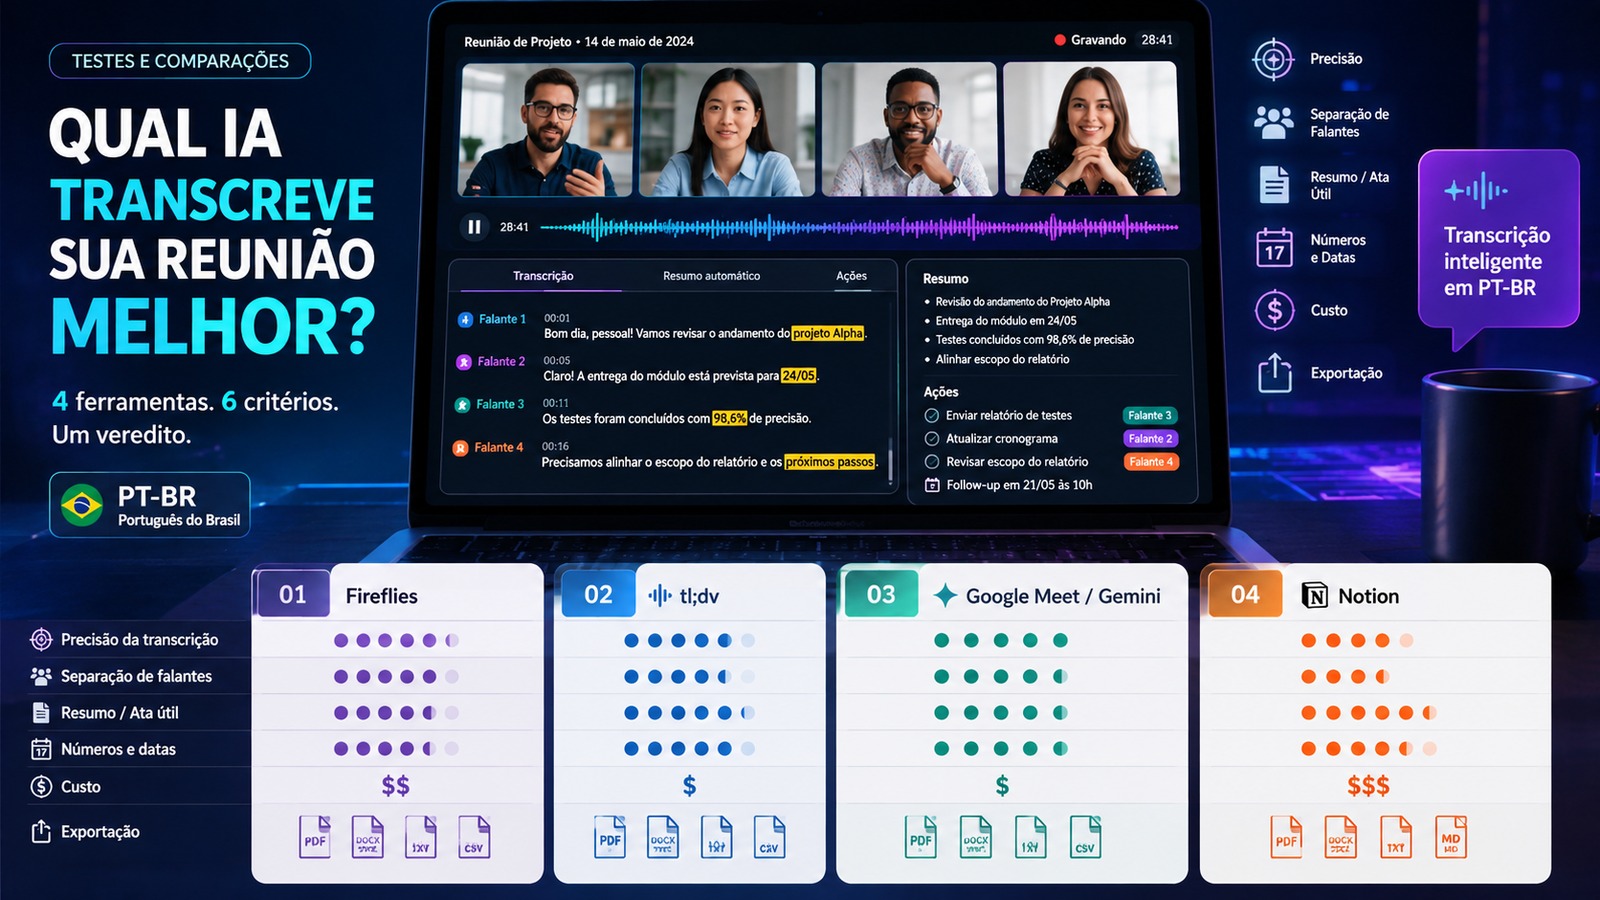
Montagem editorial com notebook exibindo reunião em vídeo, transcrição em português e quadro comparativo de Fireflies, tl;dv, Google Meet/Gemini e Notion.
Tests and Comparisons19/08/202610 min read

Which AI best transcribes meetings in Portuguese? Benchmark PT-BR of Fireflies, tl;dv, Google Meet/Gemini and Notion

Useful comparison in PT-BR requires human feedback: see what the four tools support today and how to measure precision, speakers, minutes, cost and export.

Read article
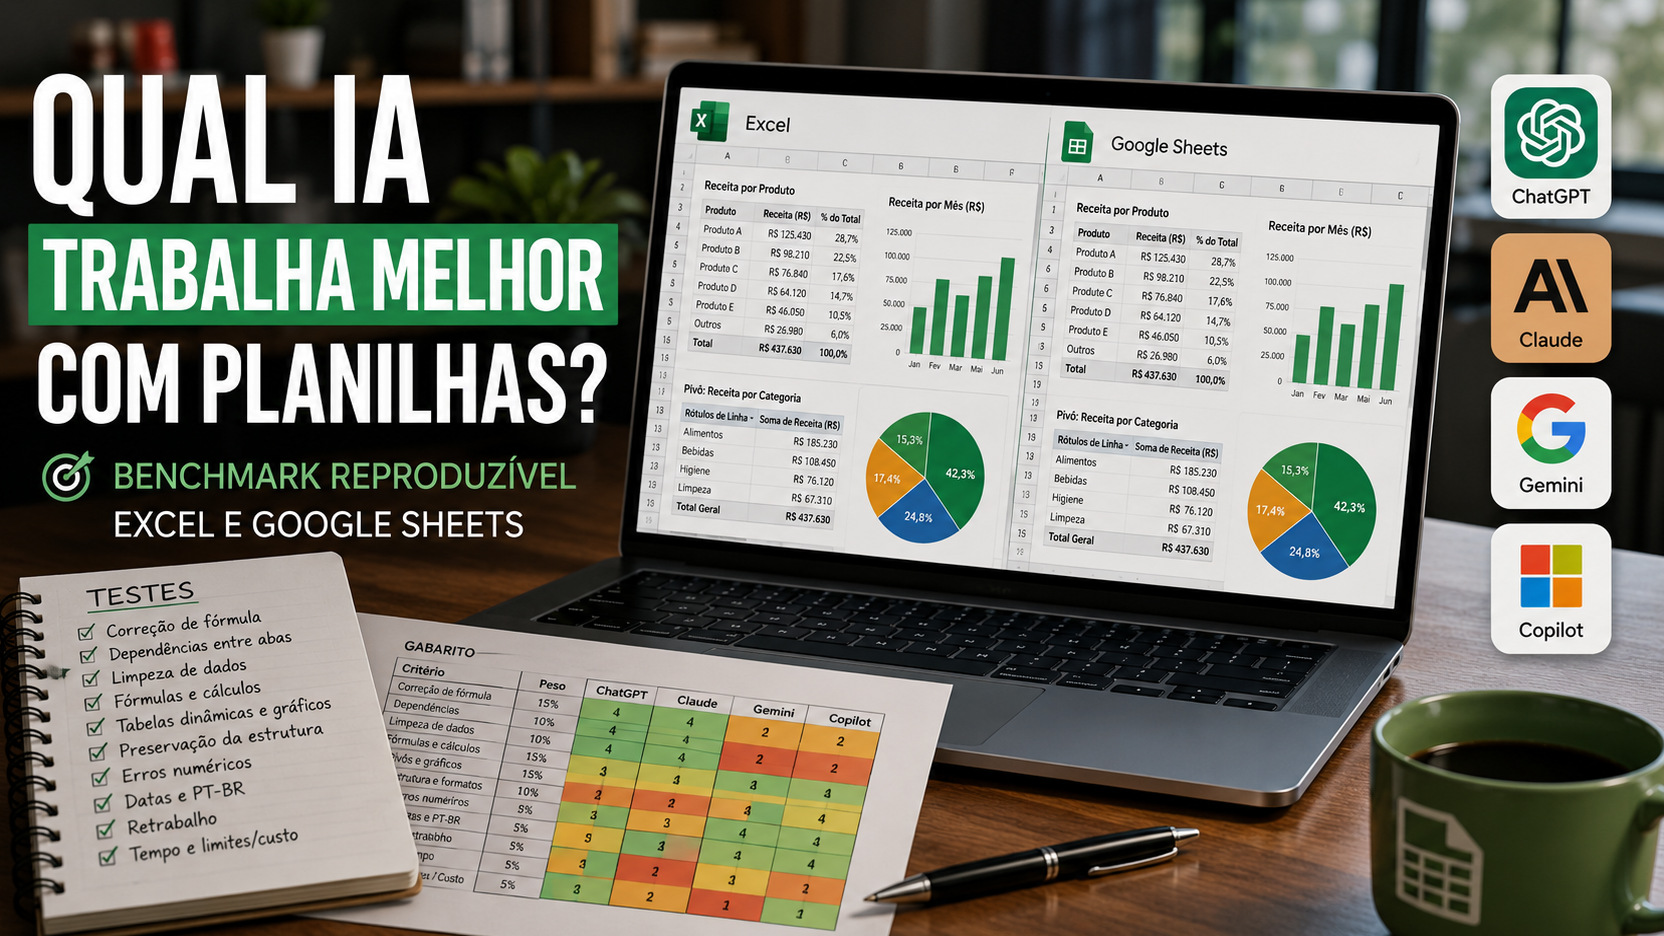
Notebook aberto em uma mesa exibindo planilhas no Excel e Google Sheets, com gráficos e tabelas; ao lado, caderno de testes, gabarito e ícones de ChatGPT, Claude, Gemini e Copilot.
Tests and Comparisons18/08/20268 min read

Which AI works best with spreadsheets? How to compare ChatGPT, Claude, Gemini and Copilot in a reproducible benchmark

A fair AI test for spreadsheets needs to measure errors, preservation of formulas and structure, rework, and context of Excel/Sheets, not just declared features.

Read article
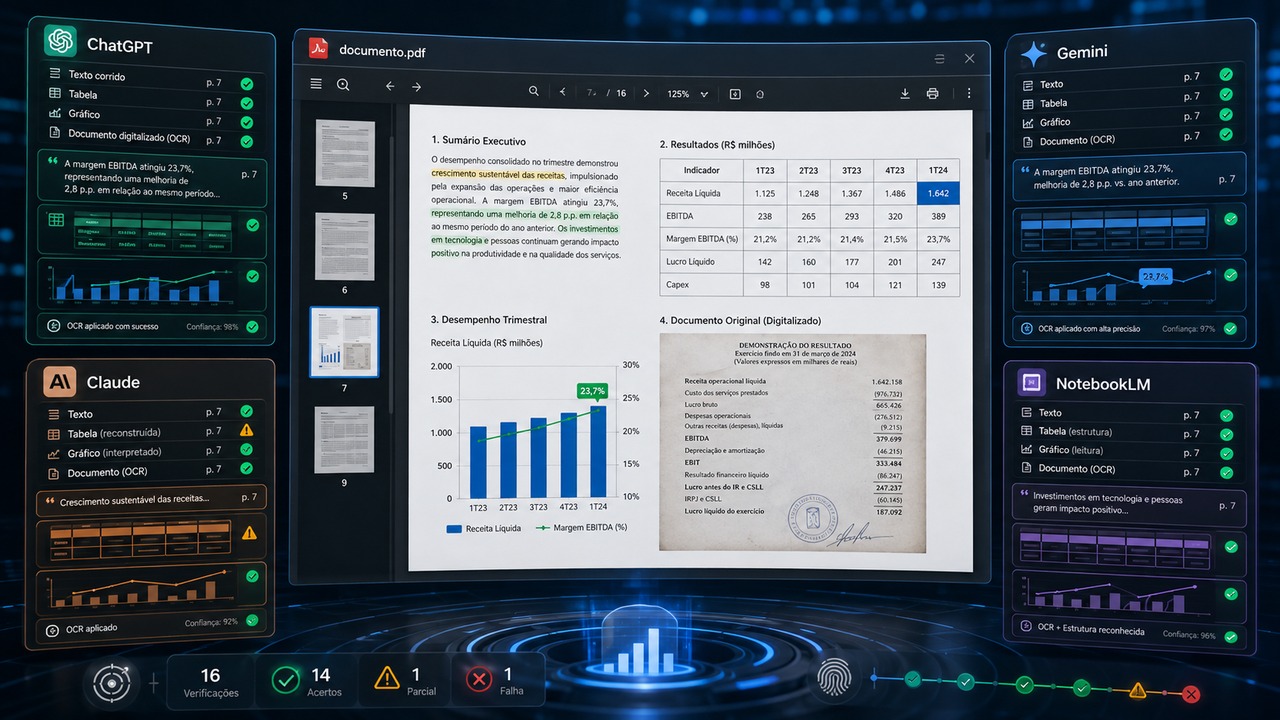
Painel comparativo em fundo escuro com um PDF central exibindo texto, tabela, gráfico e página digitalizada, cercado por quadros de ChatGPT, Claude, Gemini e NotebookLM com indicadores de acerto e OCR.
Tests and Comparisons17/08/202612 min read

Which AI analyzes PDFs best? How to test ChatGPT, Claude, Gemini and NotebookLM with a reproducible benchmark

A comparable method to test text, tables, graphs and scanned pages, measure hallucinations and find out where each tool really fails.

Read article
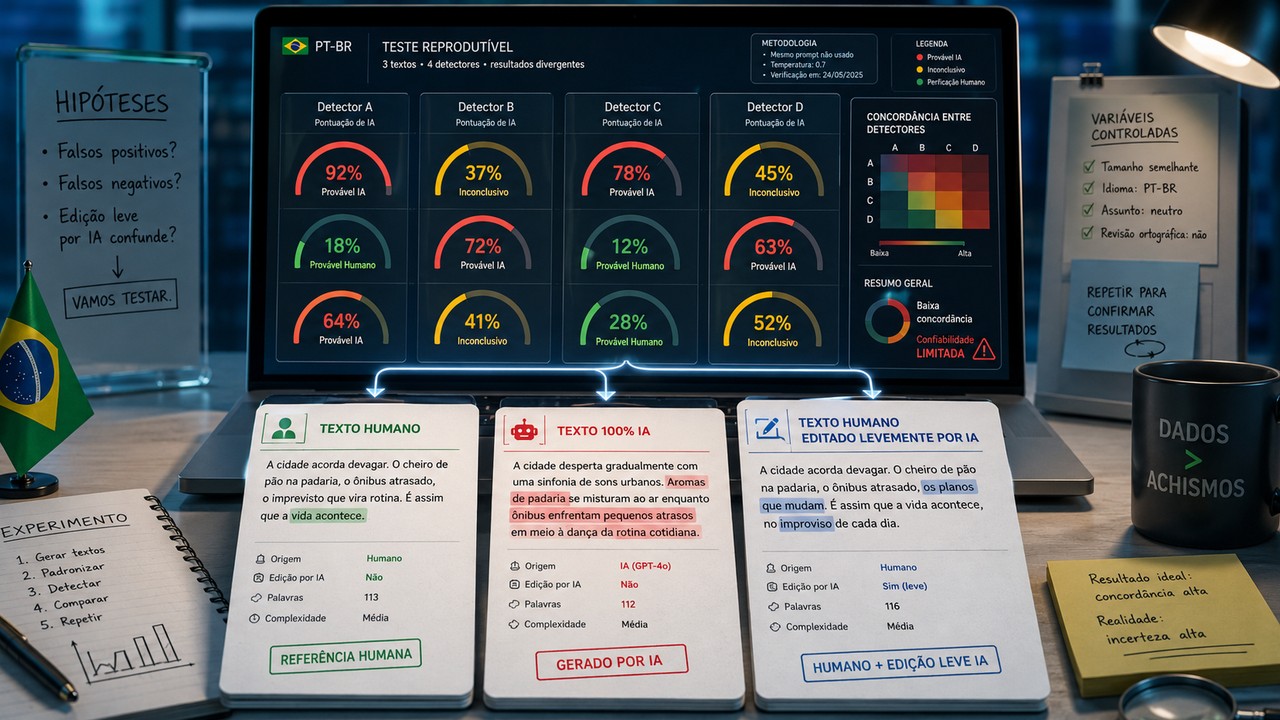
Mesa de teste com notebook exibindo pontuações divergentes de quatro detectores de IA para textos em PT-BR: humano, gerado por IA e humano editado por IA.
Tests and Comparisons16/08/202611 min read

Does AI detector work in Portuguese? What a PT-BR reproducible test needs to measure

GPTZero, Copyleaks and Winston declare support for Portuguese; Turnitin does not accept PT-BR in the AI ​​report. Understand why the score does not prove authorship and how to test...

Read article
Relatórios de pesquisa de quatro assistentes de IA comparados por cobertura, suporte e qualidade das citações.
Tests and Comparisons09/08/202610 min read

Deep Research under audit: Do ChatGPT, Claude, Gemini and Perplexity support what they cite?

Citations do not guarantee evidence. See what recent studies show about ChatGPT, Claude, Gemini, and Perplexity and how to audit research with AI.

Read article
Agente de IA diante de várias ferramentas digitais, com uma chamada destacada e um fluxo de recuperação após erro.
Tests and Comparisons08/08/20268 min read

Tool calling under pressure: which model chooses the tool best and recovers from errors?

Current comparison of tool calling shows who leads in real flows, how models deal with failures and what tests to do before taking an agent to production.

Read article
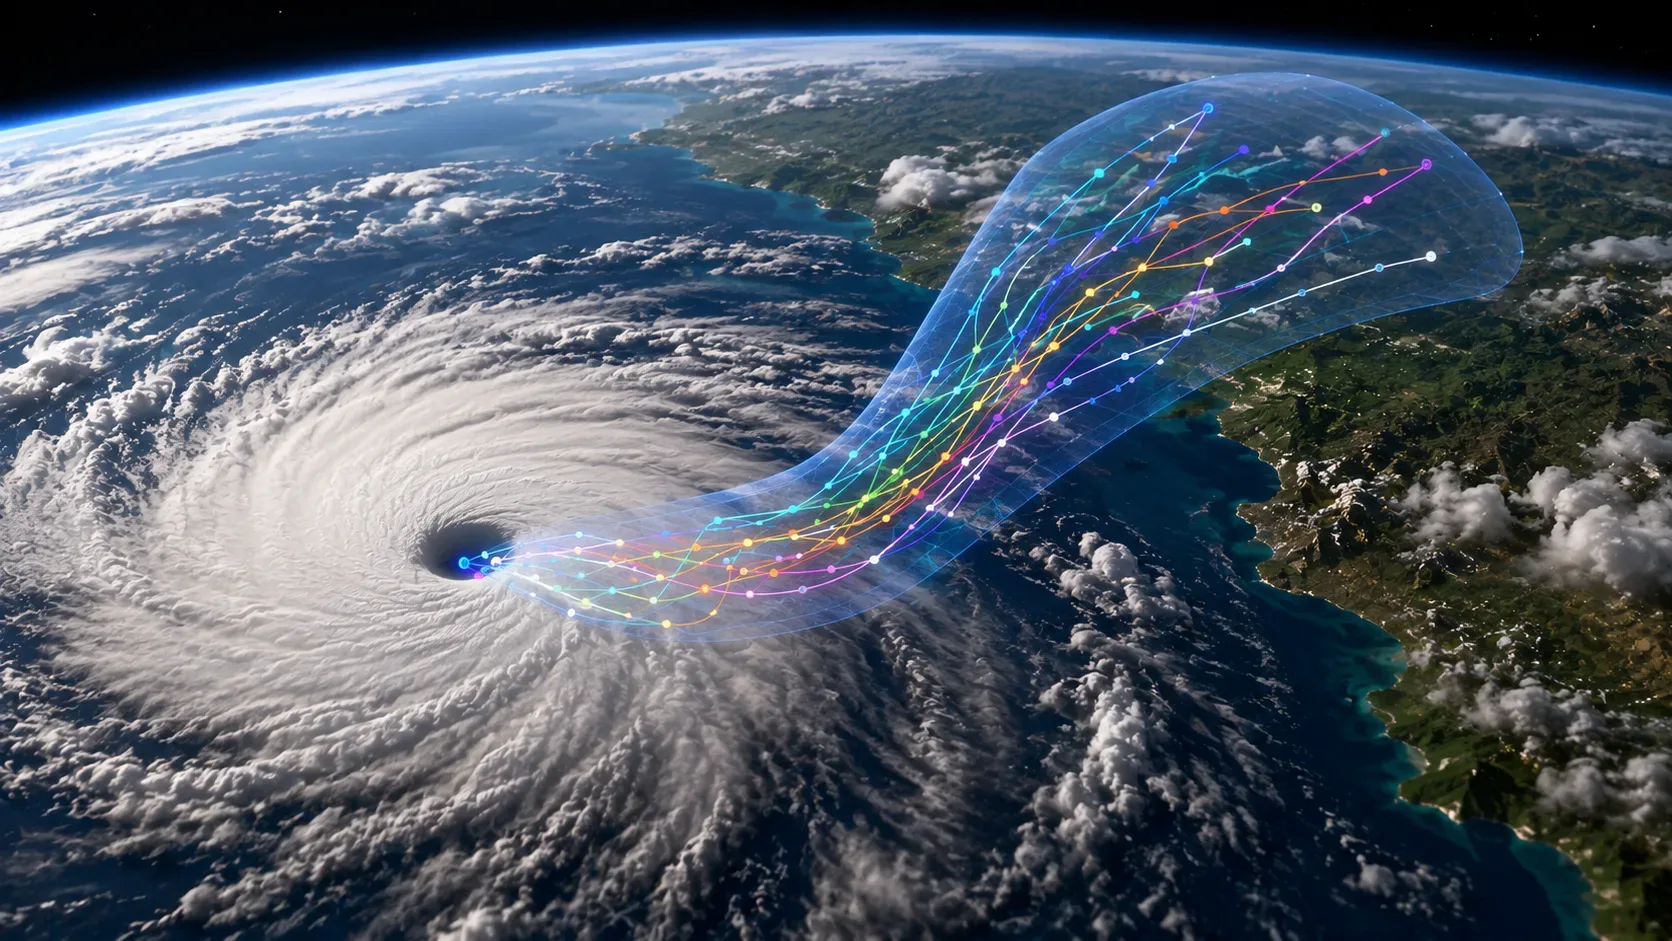
Trajetórias probabilísticas de um ciclone em vários membros de ensemble, usadas para ilustrar a incerteza da previsão.
Tests and Comparisons06/08/202610 min read

WeatherNext Cyclones gives “an extra day” to forecast cyclones? What the new study actually compared

The WeatherNext Cyclones “extra day” is an average performance advantage in benchmarks, not a guarantee. See comparisons, metrics, sample and limits.

Read article
Tabela comparando custo, latência e taxa de conclusão entre GPT-5.6 Luna, Terra e Sol
Tests and Comparisons04/08/202612 min read

GPT-5.6 Luna became 80% cheaper: when is it worth exchanging Earth or Sun?

Luna fell to a tenth of the price of Terra. See the break-even point per task, how to account for rework and when Sol still pays off.

Read article