Category

Tests and Comparisons

Reproducible assessments by task, cost, speed, accuracy and ease of use.

20articles
Mesa de pesquisa com notebook, lupa sobre um documento, robô de IA e livros identificados como fonte, edição, DOI e afirmação.
Tests and Comparisons26/09/20265 min read

How to test whether an AI assistant fabricated a reference: a verification protocol

A practical protocol for checking whether an AI-cited reference exists, whether its DOI matches the correct work, whether the edition is right, and whether the source actually supp...

Read article

Mulher em ambiente doméstico conversa com robô humanoide sentado diante dela, representando interação entre IA e apoio emocional.
Tests and Comparisons24/09/20266 min read

MentalHealthBench: what the new AI evaluation measures and what limits remain

The open benchmark evaluates AI responses across 1,215 synthetic mental health conversations. Learn its methodology, rubrics, user profiles, and limits.

Read article
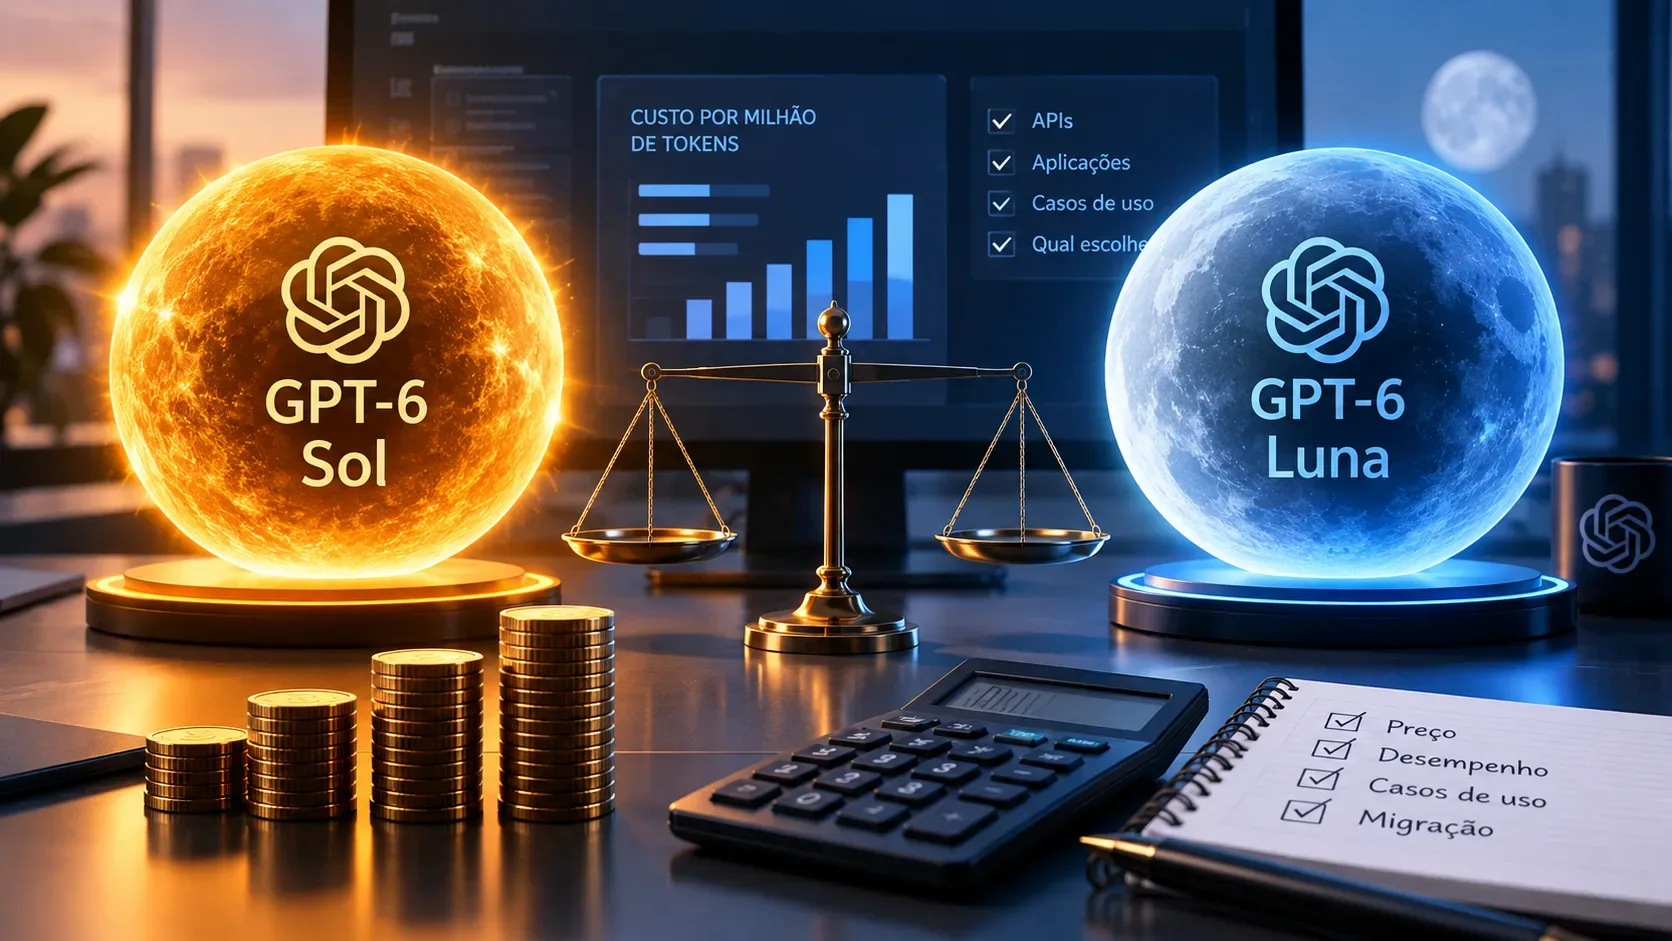
Uma esfera dourada identificada como GPT-6 Sol e uma esfera azul identificada como GPT-6 Luna aparecem em lados opostos de uma balança, com moedas e calculadora em primeiro plano.
Tests and Comparisons23/09/20265 min read

GPT-6 Sol or Luna in the API: prices per million tokens and how to choose

Compare GPT-6 Sol and Luna API prices, see a workload cost example, and understand when each model makes more sense.

Read article
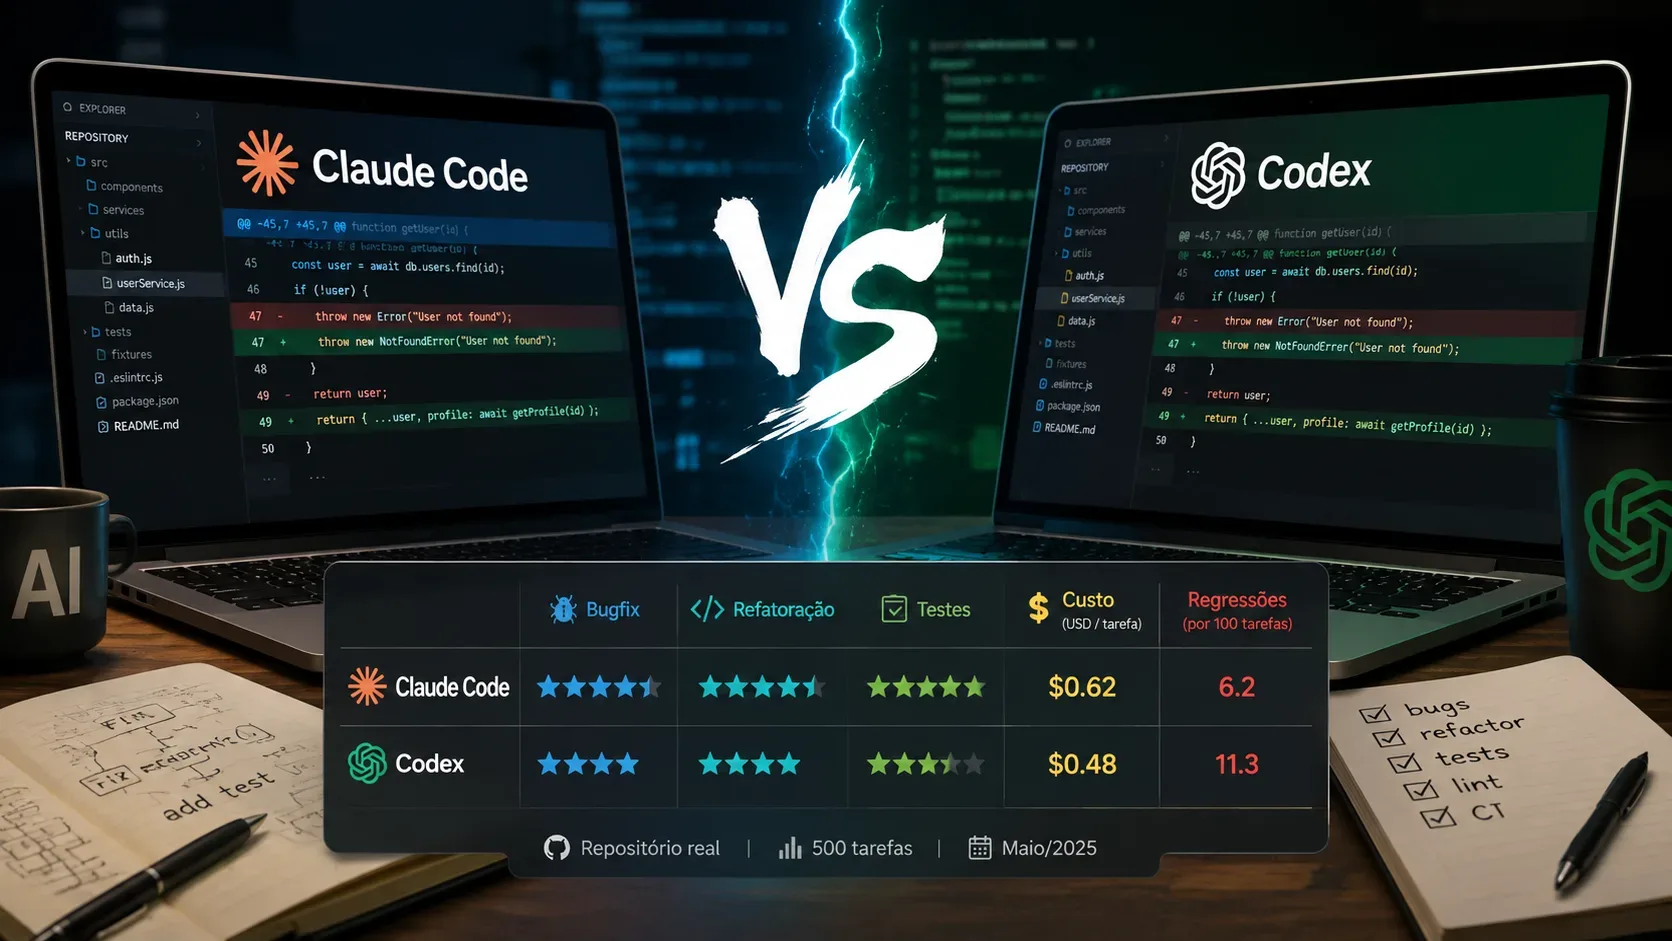
Dois notebooks lado a lado exibem diffs de código de Claude Code e Codex, com um painel comparativo de métricas ao centro.
Tests and Comparisons01/09/20267 min read

Claude Code vs Codex: which changes a repository with fewer regressions?

2026 benchmarks show a close race: Claude Code leads on aggregate quality, Codex wins on cost and speed, but regression risk still needs testing in your own repository.

Read article
Dois apresentadores diante de microfones e câmeras em composição dividida, conectados por ondas de áudio em verde, amarelo e azul.
Tests and Comparisons01/09/20267 min read

Veo 3.1 or Kling 3.0: which is better for video with Portuguese audio and dialogue?

For native Brazilian Portuguese, Veo 3.1 is the first option to test; Kling 3.0 becomes stronger when you bring a prepared Portuguese voice track for lip-sync.

Read article
Pesquisadora diante de três áreas visuais com artigos científicos, rede de citações e símbolo de verificação.
Tests and Comparisons31/08/20269 min read

Elicit, Consensus, or Scite: which finds the right papers and helps verify citations?

Elicit, Consensus, and Scite address different research stages: search and screening, evidence synthesis, and auditing citation context.

Read article
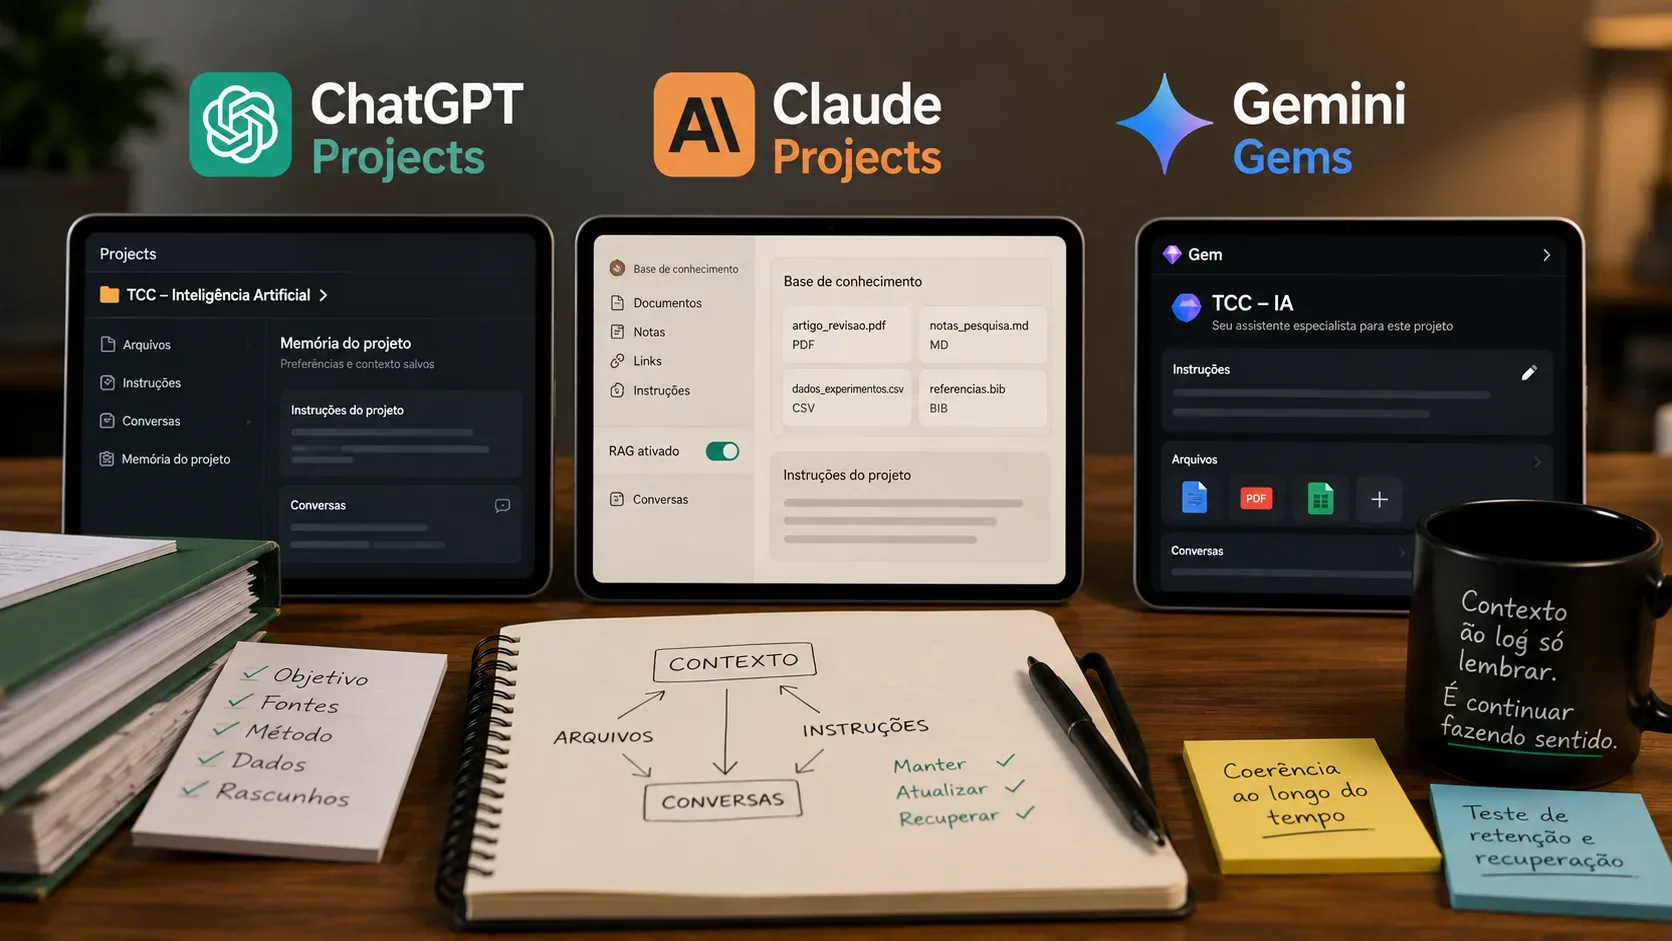
Três tablets lado a lado representam ChatGPT Projects, Claude Projects e Gemini Gems, com arquivos, instruções e anotações sobre contexto em uma mesa de trabalho.
Tests and Comparisons31/08/20268 min read

ChatGPT Projects, Claude Projects, or Gemini Gems: which keeps long-running work in context best?

A comparison focused on cross-chat continuity, information updates, instruction conflicts, and context isolation, plus a reproducible protocol for testing all three.

Read article
Mulher ao centro com jaqueta vermelha entre duas versões editadas da mesma foto, uma preservada e outra com alterações colaterais destacadas.
Tests and Comparisons31/08/20267 min read

ChatGPT or Gemini: which edits a photo without changing what you did not ask for? Fidelity benchmark for 2026

A photo-editing fidelity comparison covering faces, text, objects, framing, local selection and collateral changes in ChatGPT and Gemini.

Read article
Ilustração editorial com painéis de DeepL, Google Tradutor, ChatGPT e Gemini ao redor de um quadro de benchmark PT-BR para inglês, com critérios de fidelidade, naturalidade e checagem de erros.
Tests and Comparisons30/08/20269 min read

DeepL, Google Translate, ChatGPT or Gemini: which translates PT-BR to English better in 2026?

Current evidence does not point to a universal champion: LLMs handle context and idioms better, while dedicated translators win on predictability and control.

Read article
Painel futurista de benchmark com três modelos de IA comparando texto em português, acentos, cedilha, moeda e legibilidade, com exemplos e pontuações ilustrativas.
Tests and Comparisons28/08/20269 min read

Which AI writes text inside images better in Portuguese? ChatGPT Images 2.0, Nano Banana 2 and Ideogram 4.0

ChatGPT Images 2.0, Nano Banana 2 and Ideogram 4.0 promise better text in images, but naming a PT-BR winner requires controlled tests of accents, currency, punctuation and legibili...

Read article
Notebook em uma mesa mostra Gemini, NotebookLM, Pergunte ao YouTube e Eightify, ao lado de um cartaz sobre benchmark PT-BR e um caderno com critérios de avaliação.
Tests and Comparisons27/08/202610 min read

Which AI summarizes YouTube videos in Portuguese best? Gemini, NotebookLM, Pergunte ao YouTube, and Eightify compared

NotebookLM is strongest for tracing claims back to the transcript; Eightify makes timestamp navigation easier. Gemini and Pergunte ao YouTube are more flexible, but require checkin...

Read article
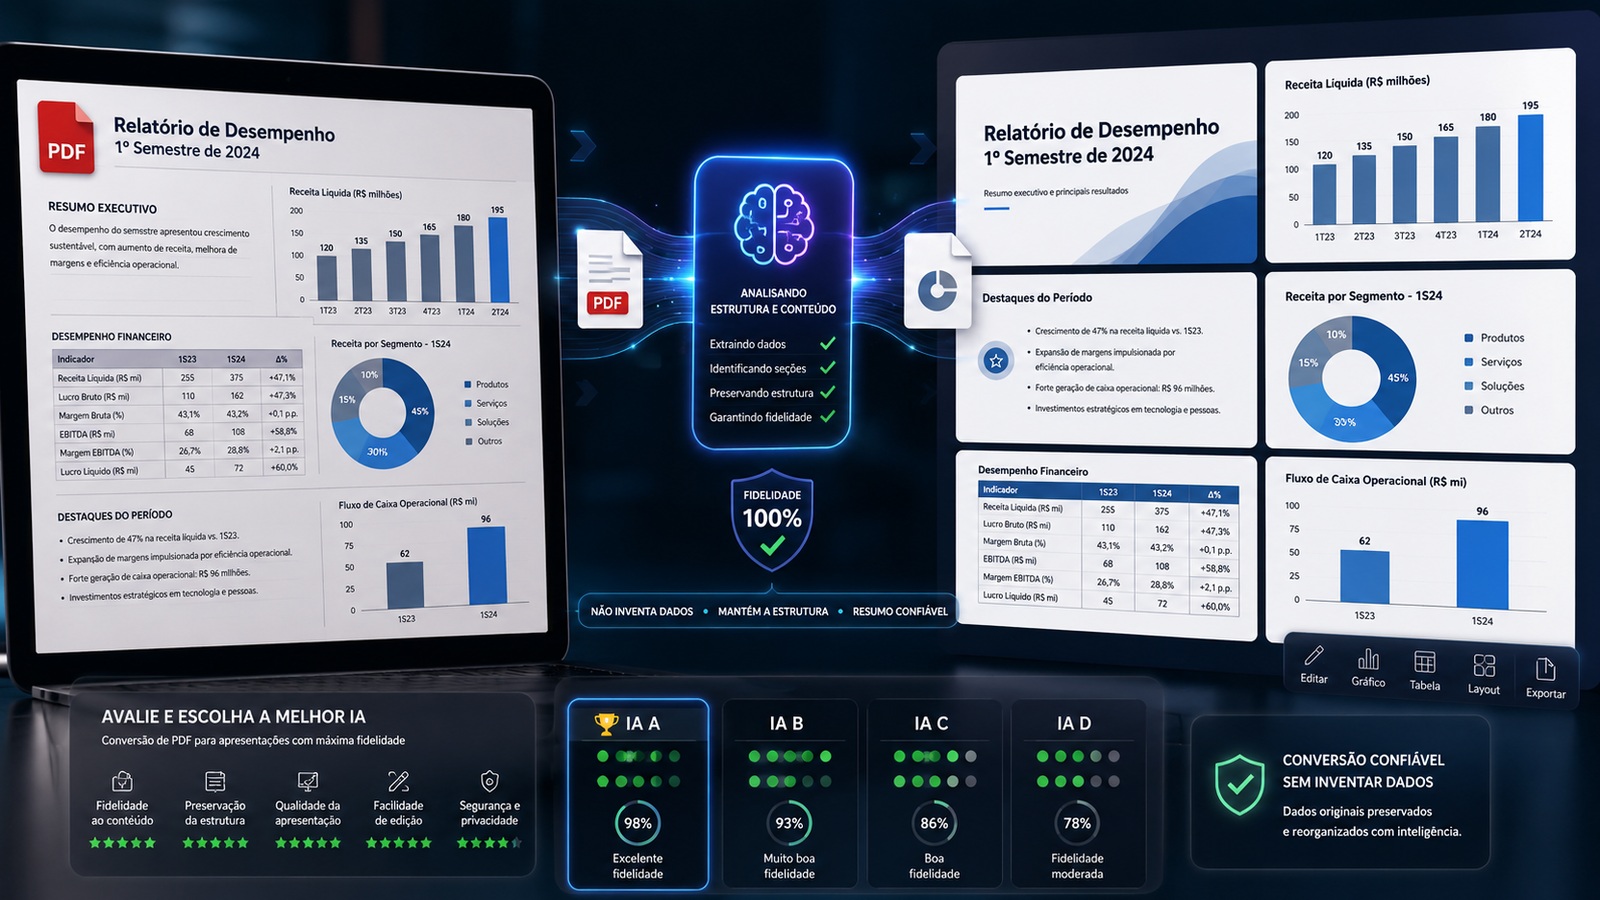
Ilustração digital mostra um PDF com gráficos à esquerda, um módulo de IA no centro e uma apresentação editável à direita, com painéis de comparação de fidelidade e preservação de dados.
Tests and Comparisons26/08/202613 min read

Which AI turns PDFs into presentations without making up data? Gamma, Plus AI, Adobe, and 2Slides in a Brazilian Portuguese benchmark

Gamma, Plus AI, Adobe Acrobat/Express, and 2Slides take different approaches to turning PDFs into slides. The best choice depends on fidelity, traceability, and editability.

Read article